SIOS SANless clusters

SIOS SANless clusters High-availability Machine Learning monitoring

  • Home
  • Products
    • SIOS DataKeeper for Windows
    • SIOS Protection Suite for Linux
  • News and Events
  • Clustering Simplified
  • Success Stories
  • Contact Us
  • English
  • 中文 (中国)
  • 中文 (台灣)
  • 한국어
  • Bahasa Indonesia
  • ไทย

Azure Site Recovery for Disaster Recovery

November 11, 2018 by Jason Aw Leave a Comment

Ensure Application Availability With Cloud-Based Disaster Recovery, Azure Site Recovery

#IGNITE2018 Session: Ensure Application Availability With Cloud-Based Disaster Recovery, Azure Site Recovery

I’m a big fan of Azure Site Recovery for Disaster Recovery  So, I was glad to attend the Ignite session today presented by Rochak Mittal and Ashish Gangwar

Ensure Application Availability With Cloud-Based Disaster Recovery, Azure Site Recovery

#IGNITE2018 Session: Ensure Application Availability With Cloud-Based Disaster Recovery, Azure Site Recovery

I’m a big fan of Azure Site Recovery for Disaster Recovery  So, I was glad to attend the Ignite session today presented by Rochak Mittal and Ashish Gangwar 

BRK3304 – Architecting mission-critical, high-performance SAP workloads on Azure

This session about ensuring Application Availability With Cloud-Based Disaster Recovery, Azure Site Recovery is particularly informative. In one of the architecture slides, they showed how an entire SAP deployment could be protected by Azure Site Recovery (ASR) and recovered in the event of a disaster in just a few minutes. Using Azure Recovery Plans allows you to have explicit control over recovery. It includes creating dependencies on resources as well as invoking scripts within a VM to help facilitate the complete recovery.

It seems like yesterday. But it was back in May of 2014 when I first started assisting Microsoft with providing a HA solution for SAP ASCS in Azure. That solution involves using DataKeeper to build a SANless cluster solution for ASCS. It still stands today as the only HA solution that also works with ASR for disaster recovery configurations such as the one shown in this demo at Ignite.
Ensure Application Availability With Cloud-Based Disaster Recovery, Azure Site Recovery 
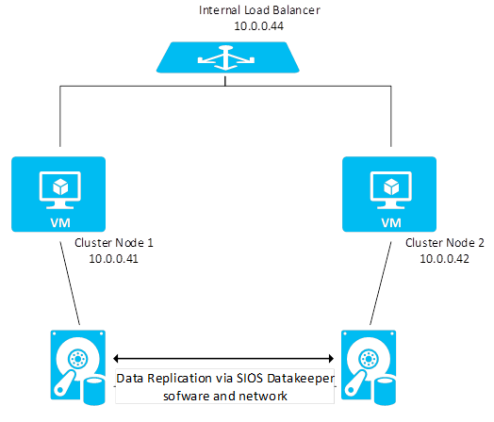
Shared disks in Azure with SIOS DataKeeper

Want to know how to Ensure Application Availability With Cloud-Based Disaster Recovery, Azure Site Recovery, let us know and we’ll be glad to help.
Reproduced with permission from Clusteringformeremortals.com
Filed Under: Clustering Simplified Tagged With: Azure Site Recovery, disaster recovery, Microsoft

Disaster Recovery For SQL Server Standard Edition

August 12, 2018 by Jason Aw Leave a Comment

Disaster recovery for SQL Server Standard Edition

Replicating A 2-Node SQL Server 2012/2014 Standard Edition Cluster To A 3rd Server For Disaster Recovery

Disaster recovery for SQL Server Standard Edition is possible with SIOS DataKeeper Cluster Edition. Here’s how.

Many people have found themselves settling for SQL Server Standard Edition due to the cost of SQL Server Enterprise Edition. SQL Server Standard Edition has many of the same features, but it comes with a few limitations. One limitation is that it does not support AlwaysOn Availability Groups. Also, it only supports two nodes in a cluster. With Database Mirroring being deprecated and only supporting synchronous replication in Standard Edition, you really have limited disaster recovery options.

Disaster recovery for SQL Server Standard Edition

One of those options is SIOS DataKeeper Cluster Edition. DataKeeper will work with your existing shared storage cluster. The software allows you to extend it to a 3rd node using either synchronous or asynchronous replication. If you are using SQL Server Enterprise, simply add that 3rd node as another cluster member for a true multisite cluster. However, since we are talking about SQL Server Standard Edition, you can’t add a 3rd node directly to the cluster. The good news is DataKeeper will allow you to replicate data to a 3rd node so your data is protected.

Disaster recovery for SQL Server Standard Edition means you are going to use DataKeeper to bring that 3rd node online as the source of the mirror. Next use SQL Server Management Studio to mount the databases that are on the replicated volumes. Your clients will also need to be redirected to this 3rd node. But it is a very cost effective solution with an excellent RPO and reasonable RTO.

The SIOS documentation talks about how to do Disaster recovery for SQL Server Standard Edition. Here, I have summarized the steps recently for one of my clients.

Configuration

  • Stop the SQL Resource
  • Remove the Physical Disk Resource From The SQL Cluster Resource
  • Remove the Physical Disk from Available Storage
  • Online Physical Disk on SECONDARY server. Add the drive letter (if not there)
  • Run emcmd . setconfiguration <drive letter> 256
    and Reboot Secondary Server. This will cause the SECONDARY server to block access to the E driver. It’s an important step because you don’t want two servers have access to the E drive at the same time, if you can avoid it.
  • Online the disk on PRIMARY server
  • Add the Drive letter if needed
  • Create a DataKeeper Mirror from Primary to DR
    You may have to wait a minute for the E drive to appear available in the DataKeeper Server Overview Report on all the servers before you can create the mirror properly. If done properly, you will create a mirror from PRIMARY to DR. As part of that process DataKeeper will ask you about the SECONDARY server which shares the volume you are replicating.

In The Event Of Disaster ….

ON DR NODE

  • Run EMCMD . switchovervolume <drive letter>
  • The first time make sure the SQL Service account has read/write access to all data and log files. You WILL have to explicitly grant this access the very first time you try to mount the databases.
  • Use SQL Management Studio to mount the databases
  • Redirect all clients to the server in the DR site. Better yet have the applications that reside in the DR site pre-configured to point to the SQL Server instance in the DR site.

AFTER DISASTER IS OVER

  • Power the servers (PRIMAY, SECONDARY) in the main site back on
  • Wait for mirror to reach mirroring state
  • Determine which node was previous source (run PowerShell as an administrator)
    get-clusterresource -Name “<DataKeeper Volume Resource name>” | get-clusterparameter
  • Make sure no DataKeeper Volume Resources are online in the cluster
  • Start the DataKeeper GUI on one cluster node. Resolve any split brain conditions (most likely there are none) ensuring the DR node is selected as the source during any split-brain recovery procedures
  • On the node that was reported as the previous source run EMCMD . switchovervolume <drive letter>
  • Bring SQL Server online in Failover Cluster Manager

The above steps assume you have SIOS DataKeeper Cluster Edition installed on all three servers (PRIMARY, SECONDARY, DR). PRIMARY and SECONDARY are a two node shared storage cluster. You are replicating data to DR which is just a standalone SQL Server instance (not part of the cluster) with just local attached storage. The Disaster Recovery Server will have a volume(s) that is the same size and drive letter as the shared cluster volume(s). This works rather well and will even let you replicate to a target that is in the cloud if you don’t have your own Disaster Recovery site configured.

You can also build the same configuration using all replicated storage if you want to eliminate the SAN completely.

Here is a nice short video that illustrates some of the possible configurations for disaster recovery for SQL Server Standard Edition. http://videos.us.sios.com/medias/aula05u2fl

Reproduced with permission from Clusteringformeremortals.com

Filed Under: Clustering Simplified, Datakeeper Tagged With: disaster recovery, disaster recovery for sql server standard edition, SQL Server Standard Edition

Meet Your Failover And Disaster Recovery Needs With SIOS

May 20, 2018 by Jason Aw Leave a Comment

Meet Your Failover And Disaster Recovery Needs With SIOS

SIOS Software Ensures 24/7 Availability, Failover And Disaster Recovery Of Theatre’s Online Ticketing System

The theatre with the highest regular annual attendance in the United Kingdom uses SIOS Protection Suite software. The software safeguard the online ticketing system keeping it available 24/7, even in the event of software bugs, hardware failure or unanticipated outages. SIOS Protection Suite meets Birmingham Hippodrome’s failover, replication and disaster recovery needs. The company moved off a hosted server and onto its own in-house networking infrastructure. By doing so, the theatre has freed itself to develop a new marketing strategy based around its website and database of customers.

The Challenge

Birmingham Hippodrome wrote a detailed specification. It called for a new network infrastructure that would deliver full failover and disaster recovery, with no single point of failure. The new infrastructure would need to be flexible and resilient. It would also need to enable them to tailor the system to improve marketing around its website and database of customers. That meant the infrastructure would essentially need to run all back office tasks. This includes a new e-mail system, the theatre’s own ticket booking, de-booking and credit card service.

The Solution

To deliver full failover and disaster recovery protection, IT infrastructure consultancy eSpida built two server rooms approximately one mile apart. Each replicating to the other. If one server failed, the other server would continue operations. They also implemented two leased lines and established two service providers at two points in the city with two separate main supplies. Birmingham wanted to simplify server “housekeeping.” The Hippodrome’s network infrastructure has been virtualised with 20 virtualised servers on IBM x3650 hardware and twin dual-core CPUs with 32 GB RAM and local disk. They use SIOS software to ensure continuous availability of applications and the online ticketing system.

SIOS Protection Suite creates a “mirrored” server system on the remote site that is identical to the primary server. If the primary server fails, SIOS software can shut it down and transfer all operations to the backup server while providing continuous access to applications and data. This capability ensures that both Birmingham Hippodrome staff and customers shopping for tickets online are unaffected by system failures or maintenance. SIOS software monitors system and application health, maintains client connectivity. It provides uninterrupted data access, giving Birmingham Hippodrome the reliable, fault-resilient system they need.

Benefit Of Failover And Disaster Recovery Solution

Another benefit of SIOS software is that installation and set-up is a quick and hassle-free process. High availability and protection of the theatre’s overall operations may have seemed like a daunting task. But SIOS Protection Suite was installed, configured, tested and in production within a few days.

For the first six months of operation, one of the servers was freezing up about once a month. In each case, SIOS software failed over to the back-up server in under a minute. The few initial instances of server failure went largely unnoticed, thanks to SIOS.

SIOS software enables Hippodrome to provide a total solution that includes hardware, installation, as well as supplementary services related to disaster recovery.

To find out more about SIOS products, go here
To read about how SIOS can meet your failover and disaster recovery needs, go here

Filed Under: Success Stories Tagged With: disaster recovery, failover, failover and disaster recovery

Agentrics Uses SIOS As Disaster Recovery And Business Continuity Solution

May 13, 2018 by Jason Aw Leave a Comment

Agentrics Uses SIOS As Disaster Recovery And Business Continuity Solution

Global Provider Of Retail And Supply Chain Solutions Uses SIOS Protection Suite For Linux For Disaster Recovery And Business Continuity Solution

Agentrics is a provider of supply chain solutions for its roster of high-profile retail customers. The company faces tremendous pressure to maintain continuous application availability. If a failure prevented their customers from accessing its solutions, their customers’ schedules and planning would be affected. Thereby potentially resulting in a loss of time and money due to failure driven delays. Agentrics had a critical need for a disaster recovery and business continuity solution to maintain the security of its important data.

The Challenge

Before implementing the SIOS solution, Agentrics relied on the high availability (HA) clustering solution that accompanied its SUN servers for data protection. The company planned to move to a Linux platform. IT staff knew they needed an HA clustering solution. They wanted something that was both easy to deploy and comparable in protection to its previous SUN clustering solution. After conducting a thorough evaluation of HA options, Agentrics chose SIOS Protection Suite for Linux for its disaster recovery and business continuity solution .

Finding A Disaster Recovery And Business Continuity Solution

SIOS Protection Suite for Linux provides continuous data availability by creating a fault resilient environment. It also incorporates application awareness capabilities that create, change, and manage availability. All these while protecting the company’s entire system stack through a single intuitive GUI. Furthermore, its application aware feature contains the ability to understand the interdependencies that occur between all system components. This is as compared to competitors whose same feature is limited to only monitoring the hardware, operating system and database.

Most Comprehensive And Scalable Solution

The SIOS solution’s advanced features make it the ideal choice for customers that are in the process of migrating their critical business applications and databases from proprietary UNIX to Linux systems. The solution’s unique makeup provides companies, such as Agentrics, many benefits. It includes the flexibility and TCO (Total Cost of Ownership) savings that are associated with open source platforms. For Agentrics, SIOS Protection Suite for Linux was a key enabler. It reduced the TCO for the migrated systems by 40 percent. In addition, SIOS Protection Suite for Linux is recognized as the industry’s most comprehensive and scalable solution for eliminating application downtime from either planned or unplanned outages. Its disaster recovery and business continuity solution operates within the most stringent SLA uptime requirements. Ranging from local data replication and application failover to complete recovery from a remote site.

Benefits

For the past four years, Agentrics has relied on SIOS Protection Suite for Linux for disaster recovery and business continuity solution. During this time the company has not experienced any critical issues thanks to the solution’s unique clustering techniques. For the handful of issues that have surfaced since the solution was deployed in Agentrics’ environment, SPS for Linux was able to immediately detect them and take the appropriate pre-defined action. As a result, Agentrics has been able to maintain uptime in excess of its SLA agreements.

To find out how SIOS products, go here
To read more about disaster recovery and business continuity solution, go here

Filed Under: Success Stories Tagged With: business continuity solution, disaster recovery, disaster recovery and business continuity solution

Automated Disaster Recovery Protection Clustering Solution For Hedge Fund 

May 6, 2018 by Jason Aw Leave a Comment

Automated Disaster Recovery Protection Clustering Solution For Hedge Fund

Automated Disaster Recovery Protection Clustering Solution For Leading International Macro Hedge Fund

netConsult Selects SteelEye LifeKeeper For Disaster Recovery Protection Clustering Solution of Exchange, Oracle9i and SQL Server Trading Systems.

netConsult is a leading consulting and systems integration provider specializing in data security management for financial services firms. It has implemented SteelEye LifeKeeper to provide automated disaster recovery protection for one of its key clients, a leading international macro hedge fund based in London, England.

Complete, Automated Disaster Recovery Protection Clustering Solution

“Due to the real-time, high-value nature of our client’s business, any kind of failure in their mission critical systems prevents them from completing timely trades. It can have significant impact upon their business. Especially,  in terms of the profitability of transactions and the confidence of their investment clients,” said Richard McDonald principal and founder of netConsult. “SteelEye LifeKeeper is one of four disaster recovery software solutions we researched on behalf of our client. The deciding factors in favor of LifeKeeper were that: it was the only truly complete, automated solution for disaster recovery. It was the only product that was capable of being demonstrated out of the box. And was by far the most reasonably priced given the complexity of our client’s environment, including the need to cluster a heterogeneous mix of storage and servers.”

Increased Server And Application Availability

“Coupled with overall heightened security concerns, it became imperative for our client to implement a comprehensive solution for business continuity. It should function reliably and efficiently. Regardless of the scale of interruption, from a simple server failure to a disaster requiring complete site recovery,” McDonald added. “We appreciated the assurance of disaster recovery protection. Additionally, our client has benefited greatly from the overall increase in server and application availability that the LifeKeeper clustering solution has made possible.”

Effectiveness & Stability Of LifeKeeper

LifeKeeper is being used to ensure complete disaster recovery protection of netConsult’s client’s core, business-critical trading systems. These include: Calypso a currency trading system based on Oracle 9i from Calypso Technology; Tradar Portfolio, also a currency trading system based on Microsoft SQL Server from Tradar Limited; and Microsoft Exchange Server, a messaging and collaboration platform being used for internal communication and confirmation of trading orders. The SteelEye LifeKeeper solution provides automated monitoring, failover and failback of these systems, coupled with integrated disk-level data replication between the customer’s primary business location in the heart of London, and its managed recovery site some distance outside of London, operated by Sungard Data Systems.

SteelEye LifeKeeper is installed on eight servers in a geographically dispersed, heterogeneous stretch-cluster configuration of four server pairs. All running the Windows 2000 operating system – four HP ProLiant BL20p G2 blade servers, accessing Hitachi Thunder 9500 V Series modular storage at the primary location. They are individually clustered over a wide-area network with four HP ProLiant DL380 G2 and DL380 G3 servers, accessing HP MSA1000 storage at the recovery site. Each of the server pairs provide individual high availability protection for the Calypso, Tradar and Exchange systems respectively. The fourth server pair ensures high availability of file and print services. The integrated, disk-level data replication capabilities within LifeKeeper enable the continuous synchronization of the server pairs. Thereby the creation of a stretch-cluster configuration to support disaster recovery over a wide area network.

Disaster Recovery Clustering of Exchange

McDonald went on to say “LifeKeeper proved to be a hands-off solution that was easy to implement in an environment known for its complexities. Since going live we have experienced several server outages. The incidents involved our client’s Oracle and SQL Server systems. LifeKeeper handled so well that no interruption or change in level of service was noticed by any users.”

In addition to the benefit of complete Disaster Recovery Protection Clustering Solution, the LifeKeeper solution has proved to be very useful during systems maintenance. Previously, it was necessary to undertake the manual and time-consuming process of configuring and manually migrating users to backup systems. Now, with LifeKeeper, production systems and user connectivity can be automatically failed over to the recovery location while maintenance is applied to the primary server. Once this task is complete, systems and users are failed back in a similar automated fashion.

“The support we have received from the SteelEye technical team during and after implementation has been excellent,” McDonald concluded. “The deployment of disaster recovery solutions for environments like Exchange and Oracle is no simple task. SteelEye continues to demonstrate a broad range of experience and knowledge, which we value greatly.”

Ensure Business Continuity

“We are excited by the selection of our SteelEye LifeKeeper Disaster Recovery solution by netConsult. The latter is a very well-respected financial services IT consultancy,” said John Banfield, European sales director for SteelEye. “The ability of the LifeKeeper solution to address their client’s critical business requirements and technical complexity is a strong validation of our approach. It is solid proof that LifeKeeper delivers industrial-strength assurance of continuity in the most demanding of environments.”

To find out how our Disaster Recovery Protection Clustering Solution can benefit you, go here.

Filed Under: Success Stories Tagged With: Business Continuity, Clustering, disaster recovery, disaster recovery protection clustering solution, Exchange

  • « Previous Page
  • 1
  • …
  • 19
  • 20
  • 21
  • 22
  • 23
  • …
  • 26
  • Next Page »

Recent Posts

  • Fail Open vs. Fail Closed: Why It’s a False Dilemma (and How True HA Fixes It)
  • The 5-Step Checklist for Validating Your Failover Setup
  • Managing an Inherited DataKeeper Cluster: Challenges and Best Practices
  • Setting Up Nginx Load Balancer on AWS
  • With Great Power: Cluster Maintenance Best Practices

Most Popular Posts

Maximise replication performance for Linux Clustering with Fusion-io
Failover Clustering with VMware High Availability
create A 2-Node MySQL Cluster Without Shared Storage
SAP for High Availability Solutions For Linux
Bandwidth To Support Real-Time Replication
The Availability Equation – High Availability Solutions.jpg
Choosing Platforms To Replicate Data - Host-Based Or Storage-Based?
Guide To Connect To An iSCSI Target Using Open-iSCSI Initiator Software
Best Practices to Eliminate SPoF In Cluster Architecture
Step-By-Step How To Configure A Linux Failover Cluster In Microsoft Azure IaaS Without Shared Storage azure sanless
Take Action Before SQL Server 20082008 R2 Support Expires
How To Cluster MaxDB On Windows In The Cloud

Join Our Mailing List

Copyright © 2026 · Enterprise Pro Theme on Genesis Framework · WordPress · Log in