SIOS SANless clusters

SIOS SANless clusters High-availability Machine Learning monitoring

  • Home
  • Products
    • SIOS DataKeeper for Windows
    • SIOS Protection Suite for Linux
  • News and Events
  • Clustering Simplified
  • Success Stories
  • Contact Us
  • English
  • 中文 (中国)
  • 中文 (台灣)
  • 한국어
  • Bahasa Indonesia
  • ไทย

High Availability & the Cloud: The More You Know

October 25, 2021 by Jason Aw Leave a Comment

High Availability & the Cloud

High Availability & the Cloud: The More You Know

While researching reasons to migrate to the cloud, you’ve probably learned that the benefits of cloud computing include scalability, reliability, availability, and more. But what, exactly, do those terms mean? Let’s consider high availability (HA), as it is often the ultimate goal of moving to the cloud for many companies.

The idea is to make your products, services, and tools accessible to your customers and employees at any time from anywhere using any device with an internet connection. That means ensuring your critical applications are operational – even through hardware failures, software issues, human errors, and sitewide disasters – at least 99.99% of the time (that’s the definition of high availability).

While public cloud providers typically guarantee some level of availability in their service level agreements, those SLAs only apply to the cloud hardware. There are many reasons for application downtime that aren’t covered by SLAs. For this reason, you need to protect these applications with clustering software that will detect issues and reliably move operations to a standby server if necessary. As you plan what and how you will make solutions available in the cloud, remember that it is important that your products and services and cloud infrastructure are scalable, reliable, and available when and where they are needed.

Quick Stats on High Availability in the Cloud in 2021

Now that we’ve defined availability in the cloud context, let’s look at its impact on organizations and businesses. PSA, these statistics may shock you, but don’t fret. We’ve also got some solutions to these pressing and costly issues.

  1. As much as 80% of Enterprise IT will move to the cloud by 2025 (Oracle).
  2. The average cost of IT downtime is between $5,600 and $11,600 per minute (Gartner; Comparitech).
  3. Average IT staffing to employee ratio is 1:27 (Ecityworks).
  4. 22% of downtime is the result of human error (Cloudscene).
  5. In 2020, 54% of enterprises’ cloud-based applications moved from an on-premises environment to the cloud, while 46% were purpose-built for the cloud (Forbes).
  6. 1 in 5 companies don’t have a disaster recovery plan (HBJ).
  7. 70% of companies have suffered a public cloud data breach in the past year (HIPAA).
  8. 48% of businesses store classified information on the cloud (Panda Security).
  9. 96% of businesses experienced an outage in a 3-year period (Comparitech).
  10.  45% of companies reported downtime from hardware failure (PhoenixNAP).

What You Can Do – Stay Informed

If you are interested in learning the fundamentals of availability in the cloud or hearing about the latest developments in application and database protection, join us. The SIOS Cloud Availability Symposium is taking place Wednesday, September 22nd (EMEA) and Thursday, September 23rd (US) in a global virtual conference format for IT professionals focusing on the availability needs of the enterprise IT customer. This event will deliver the information you need on application high availability clustering, disaster recovery, and protecting your applications now and into the future.

Cloud Symposium Speakers & Sessions Posted

We have selected speakers presenting a wide range of sessions supporting availability for multiple areas of the data application stack. Check out the sessions posted and check back for additional presentations to be announced! Learn more

Register Now

Whether you are interested in learning the fundamentals of availability in the cloud or hearing about the latest developments in application and database protection, this event will deliver the information you need on application high availability clustering, disaster recovery, and protecting your applications now and into the future.

Register now for the SIOS Cloud Availability Symposium.

Reproduced from SIOS
Filed Under: Clustering Simplified Tagged With: Application availability, Cloud, cloud migration, disaster recovery, High Availability

Disaster Recovery Made Simple

October 22, 2021 by Jason Aw Leave a Comment

Disaster Recovery Made Simple

Disaster Recovery Made Simple

Disaster Recovery Made Simple

Heard the term disaster recovery (DR) thrown around often? DR is a strategy and set of policies, procedures, and tools. It ensures critical IT systems, databases, and applications continue to operate and be available to users when a man-made or natural disaster happens. It typically involves moving application operation to a redundant DR environment that is geographically separated from the primary environment. While the IT team owns the disaster recovery strategy, DR is an important component of every organization’s Business Continuity Plan. The latter is a strategy and set of policies, procedures, and tools to ensure business operations continue through an interruption in service.

It may sound confusing at first. But we’ve collected some quick facts to make disaster recovery simple to understand:

Point 1. Implement an IT disaster recovery or a disaster recovery plan (DRP)

A DRP is a strategy and set of policies, procedures, and tools that ensure critical IT systems, databases, and applications continue to operate and be available to users when a disaster strikes the organization’s primary computing environment. While the IT team owns the disaster recovery strategy, DR is an important component of every organization’s Business Continuity Plan.

Point 2. Ensure Geographic Separation

An essential part of application disaster recovery is ensuring there is a redundant, geographically separated application environment available. You have either efficient, block level replication and or a clustering software that can failover operation to it in the event of a disaster. If your application is running in a cloud, your clustering environment should failover across cloud regions and availability zones for disaster recovery.

Point 3. Test, test, and test some more

In a recent Spiceworks survey, 59 percent of organizations indicated they had experienced one to three outages (that is, any interruption to normal levels of IT-related service) over the course of one year. 11 percent have experienced four to six. 7 percent have experienced seven or more. In short, a DR event is nearly inevitable. Be sure you conduct regular testing to ensure you know exactly what will happen when it does.

Point 4. Understand Your Risk

The disaster in DR does not need to be a full-fledged hurricane, tornado, flood, or earthquake that impacts your business. Disasters come in many forms, including a cyber-attack, fire, theft, or vandalism. In fact, simple human error still rates among the leading causes of IT data center downtime. In short, a disaster is any crisis that results in a down system for a long duration and/or major data loss on a large scale that impacts your IT infrastructure, data center, and your business.

Point 5. Ensure Your DRP has a Checklist

It should include critical IT systems and network prioritized by their expected time for recovery (RTO). Document the steps needed to restart, reconfigure and recover systems and networks. Employees should know where to locate the DRP and how to execute basic emergency steps in the event of an unforeseen incident.

Point 6. Substantiate DRPs through testing

DRPs should identify deficiencies and provides opportunities to fix problems before a disaster occurs. Testing can offer proof that the plan is effective and that it will enable you to meet recovery point and recovery time objectives (RPOs and RTOs). Since IT systems and technologies are constantly changing, DR testing also helps ensure a disaster recovery plan is up to date.

Choose a failover clustering technology that makes DR testing simple by facilitating fast, simple, reliable switchover of application operation to DR nodes and back.

When you look at those statistics, you know you are living on borrowed time if you don’t have a disaster recovery plan in place. The SIOS disaster recovery solution is a multi-site, geographically dispersed cluster that meets RPO and  RTOs with ease. What makes SIOS different from many other DR providers is that it offers one solution that meets both high availability and disaster recovery needs. To learn more about our DR solutions, check out the insights page here.

Reproduced with permission from SIOS

Filed Under: Clustering Simplified Tagged With: cluster, clusters, disaster recovery, RPO, RTO

RTO vs. RPO: Learning the Difference to Achieve Your Operational Goals

October 10, 2021 by Jason Aw Leave a Comment

RTO vs RPO Learning the Difference to Achieve Your Operational Goals

RTO vs. RPO: Learning the Difference to Achieve Your Operational Goals

In addition to 99.99% availability time, high availability environments also need to meet stringent recovery time and recovery point objectives, RTO and RPO, respectively. RTO and RPO are two key parameters that businesses should define before creating their business continuity and disaster recovery plans. Both metrics help to design the recovery process, and to define the recovery time limits, the frequency of backups, and the recovery procedures. Although RTO and RPO may seem alike, there are core differences you should consider. Read on to understand the difference between RTO vs. RPO.

To be clear, RTO is a measure of the time elapsed from application failure to restoration of application operation. It is a measure that dictates how much time you have to recover after disaster strikes. On the other hand, RPO is a measure of how up-to-date the data is when application availability has been restored after a downtime issue. It is often described as the maximum amount of data loss that can be tolerated when a failure happens.

Things to consider for evaluating your disaster recovery plan

First, it’s important to define the criticality of the application and its associated data to core business operations. How much does a minute of downtime or data loss for this application cost the company? Next, consider the potential set of disasters against which you would like to protect your organization. Some disasters that require data recovery and backup include:

  • Data loss: This may be as simple as someone deleting a folder, or as complex as a case of ransomware or an infected database.
  • Application loss: This refers to when changes to security, an update, or system configurations negatively impact services.
  • System loss: This includes when hardware fails, or, virtual server crashes.
  • Datacenter loss: This includes data centers that are on-premises and in public clouds
  • Business location loss: In this instance, a disaster might include an electrical outage, fire, flooding, or even a chemical spill outside the building. The business facilities require recovery to an alternate location.

Reducing an organization’s RPO and RTO

It’s important to consider the RTO and RPO as they apply to different types of data. Organizations that do a file-level backup of a database, rather than investing in an offsite virtual environment, will see longer recovery times and limits to how recently updated that data will be once recovered.

Consider the possible disasters, match them with the data sets that need to be protected, and then identify the recovery objectives. These steps will then provide you the information necessary to build tactical backup solutions that meet your recovery time objective and recovery point objective.

What is RTO and RPO in SQL Server?

SQL Server allows users to set up automated log backups to be restored from a standby server. With this log shipping, users can recover a fairly recent database copy—depending on the RTO and RPO of that process. Those RTO and RPO requirements are set by users, depending on their needs, budget, and any technological network limitations.

However, SQL Server RTO and RPO are not necessarily straightforward. In many cases, the process isn’t as fast as a client may imagine. They may have an ideal RPO in mind, but slow network speeds or an incorrectly configured backup can throttle this process. In addition, restoring a log backup in this way can involve transferring large amounts of data, and this process can easily exceed the determined acceptable RTO.

Since SQL Server is typically a business-critical application, customers can easily justify HA/DR protection for it – usually in the form of a failover cluster that can failover across cloud availability zones and regions for disaster recovery. This can be accomplished easily by adding SIOS DataKeeper to a Windows Server Failover Clustering environment or by using SIOS Protection Suite in a Linux environment. Both of these solutions will deliver not only 99.99% availability but also RPO of zero and RTO of mere seconds.

Now that you know…

Ultimately, data loss prevention for business continuity is a crucial requirement for any business. Take the time to consider how you will meet your RTO and RPO goals, no matter how large or small your business is, or what internal IT operations you support. SIOS high availability clusters deliver an RPO of zero and an RTO of mere minutes.

Learn more about SIOS DataKeeper for Windows or SIOS Protection Suite for Linux

To request a free trial, let us know here.

Reproduced from SIOS

Filed Under: Clustering Simplified Tagged With: disaster recovery, RPO, RTO, SQL Server

Deployment of a SQL Server Failover Cluster Instance on Huawei Cloud

September 28, 2021 by Jason Aw Leave a Comment

Huawei Cloud high availability ECS IaaS

Deployment of a SQL Server Failover Cluster Instance on Huawei Cloud

*DISCLAIMER: While the following completely covers the high availability portion within the scope of our product, this is a setup “guide” only and should be adapted to your own configuration.

Overview

HUAWEI CLOUD is a leading cloud service provider not just in China but also has global footprint with many datacenters around the world. They bring Huawei’s 30-plus years of expertise together in ICT infrastructure products and solutions and are committed to providing reliable, secure, and cost-effective cloud services to empower applications, harness the power of data, and help organizations of all sizes grow in today’s intelligent world. HUAWEI CLOUD is also committed to bringing affordable, effective, and reliable cloud and AI services through technological innovation.

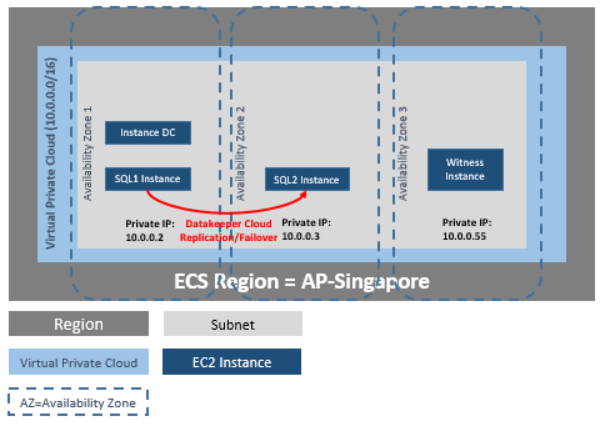
DataKeeper Cluster Edition provides replication in a virtual private cloud (VPC) within a single region across availability zones for the Huawei cloud. In this particular SQL Server clustering example, we will launch four instances (one domain controller instance, two SQL Server instances and a quorum/witness instance) into three availability zones.

Huawei Cloud SIOS Datakeeper HA Architecture

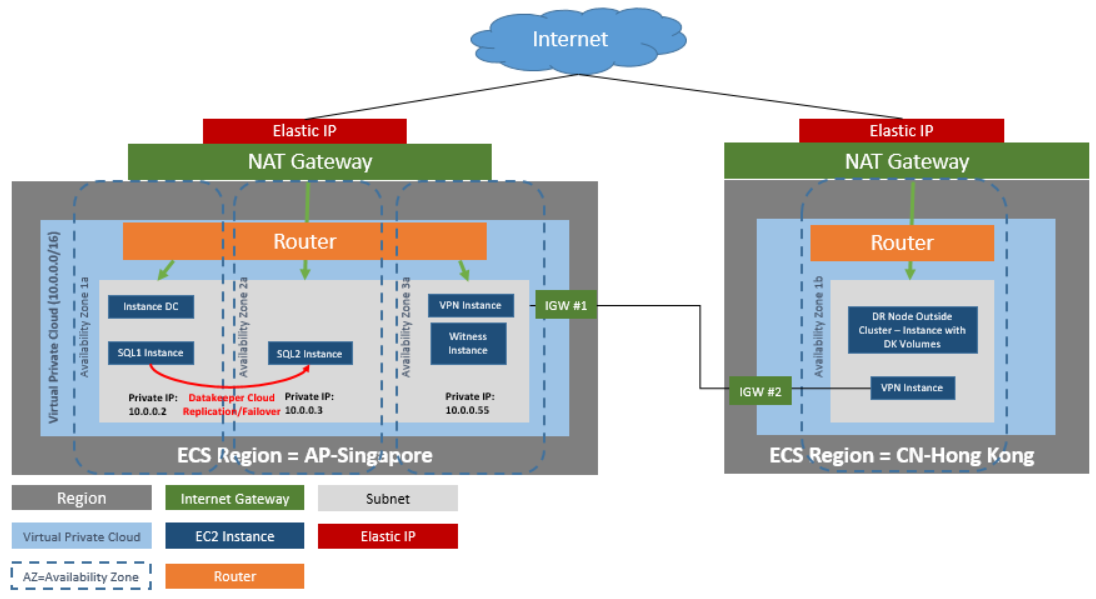
DataKeeper Cluster Edition provides support for a data replication node outside of the cluster with all nodes in Huawei cloud. In this particular SQL Server clustering example, four instances are launched (one domain controller instance, two SQL Server instances and a quorum/witness instance) into three availability zones. Then an additional DataKeeper instance is launched in a second region including a VPN instance in both regions. Please see Configuration of Data Replication From a Cluster Node to External DR Site for more information. For additional information on using multiple regions please see Connecting Two VPCs in Different Regions.

Huawei Cloud SIOS Datakeeper DR architecture

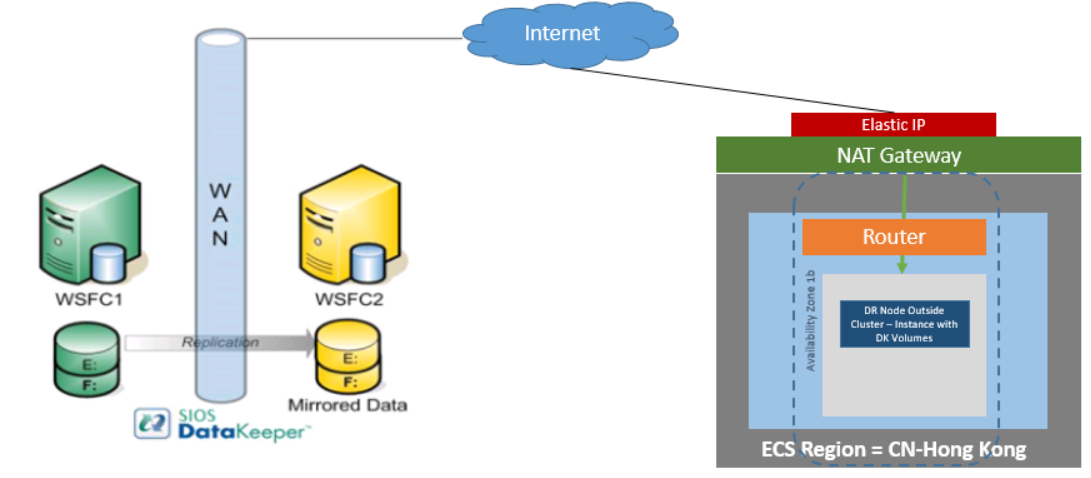
DataKeeper Cluster Edition also provides support for a data replication node outside of the cluster with only the node outside of the cluster in Huawei Cloud. In this particular SQL Server clustering example, WSFC1 and WSFC2 are in an on-site cluster replicating to a Huawei Cloud instance. Then an additional DataKeeper instance is launched in a region in Huawei Cloud. Please see Configuration of Data Replication From a Cluster Node to External DR Site for more information.

Huawei Cloud SIOS Datakeeper Hybrid DR Architecture

Requirements

Description Requirement
Virtual Private Cloud In a single region with three availability zones
Instance Type Minimum recommended instance type: s3.large.2
Operating System See the DKCE Support Matrix
Elastic IP One elastic IP address connected to the domain controller
Four instances One domain controller instance, two SQL Server instances and one quorum/witness instance
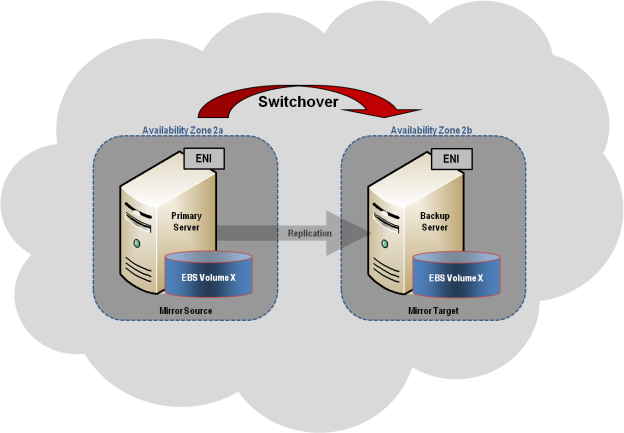
Each SQL Server ENI (Elastic Network Interface) with 4 IPs

·         Primary ENI IP statically defined in Windows and used by DataKeeper Cluster Edition

·         Three IPs maintained by ECS while used by Windows Failover Clustering , DTC and SQLFC

Volumes Three volumes (EBS and NTFS only)

·         One primary volume (C drive)

·         Two additional volumes

o    One for Failover Clustering

o    One for MSDTC

Release Notes

Before beginning, make sure you read the DataKeeper Cluster Edition Release Notes for the latest information. It is highly recommended that you read and understand the DataKeeper Cluster Edition Installation Guide.

Create a Virtual Private Cloud (VPC)

A virtual private cloud is the first object you create when using DataKeeper Cluster Edition.

*A virtual Private Cloud (VPC) is an isolated private cloud consisting of a configurable pool of shared computing resources in a public cloud.

  1. Using the email address and password specified when signing up for Huawei Cloud, sign in to the Huawei Cloud Management Console.
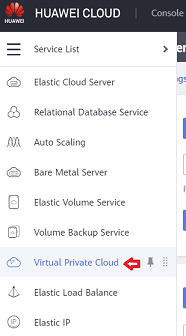
  2. From the Services dropdown, select Virtual Private Cloud.

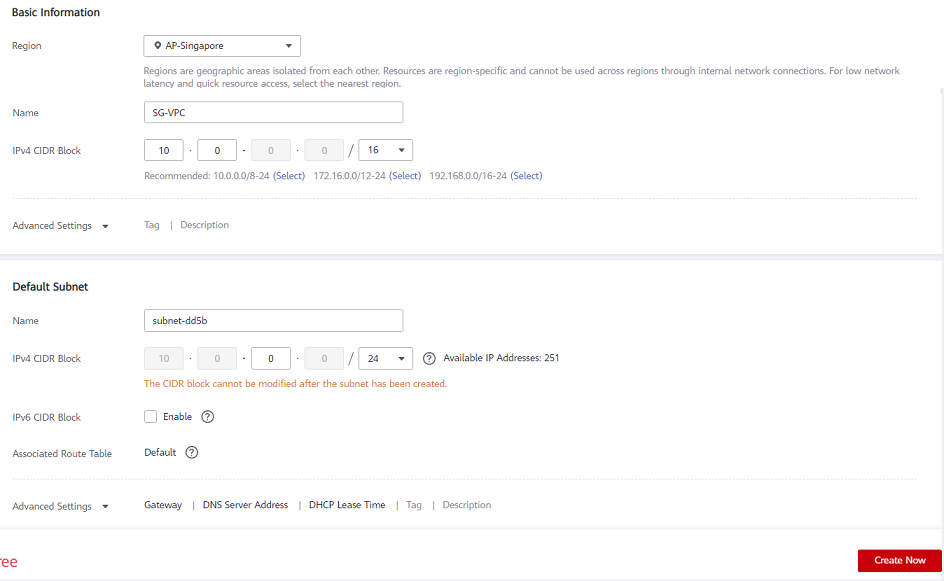
  1. On the right side of the screen, click on Create VPC and select the region that you want to use.
  2. Input the name that you want to use for the VPC
  3. Define your virtual private cloud subnet by entering your CIDR (Classless Inter-Domain Routing) as described below
  4. Input the subnet name, then click Create Now.

*A Route Table will automatically be created with a “main” association to the new VPC. You can use it later or create another Route Table.

*HELPFUL LINK:
Huawei’s Creating a Virtual Private Cloud (VPC)

Launch an Instance

The following walks you through launching an instance into your subnet. You will want to launch two instances into one availability zone, one for your domain controller instance and one for your SQL instance. Then you will launch another SQL instance into another availability zone and a quorum witness instance into yet another availability zone.

*HELPFUL LINKS:
Huawei Cloud ECS Instances

  1. Using the email address and password specified when signing up for Huawei Cloud, sign in to the Huawei Cloud Management Console.
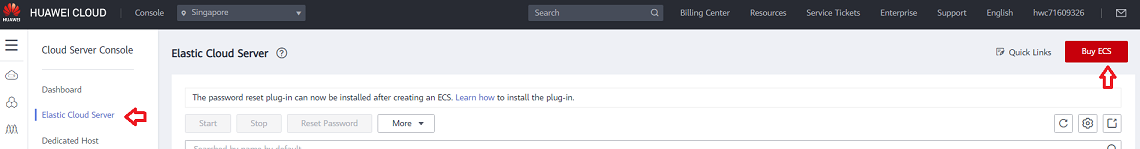
  2. From the Service List dropdown, select Elastic Cloud Server.

  1. Select Buy ECS button and choose the Billing Mode, Region and AZ (Availability Zone) to deploy the Instance
  2. Select your Instance Type. (Note:Select s3.large.2 or larger.).
  3. Choose an Image. Under Public Image, select the Windows Server 2019 Datacenter 64bit English image
    1. For Configure Network, select your VPC.
    2. For Subnet, select an Subnet that you want to use, select Manually-specified IP address and input the IP address that you want to use
    3. Select the Security Group to use or Edit and select an existing one.
    4. Assign an EIPif you need the ECS instance to access the internet
    5. Click Configure Advanced Settings and provide a name for the ECS, use Password for Login Mode and provide the secure password for Administrator login
    6. Click Configure Now on Advanced Options Add a Tag to name your instance and Click on Confirm
  4. Perform final review of the Instance and click on Submit.

*IMPORTANT: Make a note of this initial administrator password. It will be needed to log on to your instance.

Repeat the above steps for all instances.

Connect to Instances

You can connect to your domain controller instance via Remote Login from the ECS pane.

Login as administrator and enter your administrator password.

*BEST PRACTICE: Once logged on, it is best practice to change your password.

Configure the Domain Controller Instance

Now that the instances have been created, we started with setting up the Domain Service instance.

This guide is not a tutorial on how to set up an Active Domain server instance. We recommend reading articles on how to set up and configure an Active Directory server. It is very important to understand that even though the instance is running in a Huawei cloud, this is a regular installation of Active Directory.

Static IP Addresses

Configure Static IP Addresses for your Instances

  1. Connect to your domain controller instance.
  2. Click Start/ Control Panel.
  3. Click Network and Sharing Center.
  4. Select your network interface.
  5. Click Properties.
  6. Click Internet Protocol Version 4 (TCP/IPv4), then Properties.
  7. Obtain your current IPv4 address, default gateway and DNS server for the network interface from Amazon.
  8. In the Internet Protocol Version 4 (TCP/IPv4) Properties dialog box, under Use the following IP address, enter your IPv4 address.
  9. In the Subnet mask box, type the subnet mask associated with your virtual private cloud subnet.
  10. In the Default Gateway box, type the IP address of the default gateway and then click OK.
  11. For the Preferred DNS Server, enter the Primary IP Address of Your Domain Controller(ex. 15.0.1.72).
  12. Click Okay, then select Close. Exit Network and Sharing Center.
  13. Repeat the above steps on your other instances.

Join the Two SQL Instances and the Witness Instance to Domain

*Before attempting to join a domain make these network adjustments. On your network adapter, Add/Change the Preferred DNS server to the new Domain Controller address and its DNS server. Use ipconfig /flushdns to refresh the DNS search list after this change. Do this before attempting to join the Domain.

*Ensure that Core Networking and File and Printer Sharing options are permitted in Windows Firewall.

  1. On each instance, click Start, then right-click Computer and select Properties.
  2. On the far right, select Change Settings.
  3. Click on Change.
  4. Enter a new Computer Name.
  5. Select Domain.
  6. Enter Domain Name– (ex. docs.huawei.com).
  7. Click Apply.

*Use Control Panel to make sure all instances are using the correct time zone for your location.

*BEST PRACTICE: It is recommend that the System Page File is set to system managed (not automatic) and to always use the C: drive.

Control Panel > Advanced system settings > Performance > Settings > Advanced > Virtual Memory. Select System managed size, Volume C: only, then select Set to save.

Assign Secondary Private IPs to the Two SQL Instances

In addition to the Primary IP, you will need to add three additional IPs (Secondary IPs) to the elastic network interface for each SQL instance.

  1. From the Service List dropdown, select Elastic Cloud Server.
  2. Click the instance for which you want to add secondary private IP addresses.
  3. Select NICs > Manage Virtual IP Address.
  4. Click on Assign Virtual IP address and select Manual enter an IP address that is within the subnet range for the instance (ex. For 15.0.1.25, enter 15.0.1.26). Click Ok.
  5. Click on the More dropdown on the IP address row, and select Bind to Server, select the server to bind the IP address to, and the NIC card.
  6. Click OK to save your work.
  7. Perform the above on both SQL Instances.

*HELPFUL LINKS:
Managing Virtual IP Addresses
Binding a Virtual IP Address to an EIP or ECS

Create and Attach Volumes

DataKeeper is a block-level volume replication solution and requires that each node in the cluster have additional volume(s) (other than the system drive) that are the same size and same drive letters. Please review Volume Considerations for additional information regarding storage requirements.

Create Volumes

Create two volumes in each availability zone for each SQL server instance, a total of four volumes.

  1. From the Service List dropdown, select Elastic Cloud Server.
  2. Click the instance for which you want to manage
  3. Go to the Disks tab
  4. Click Add Disk to add a new volume of your choice and size, make sure you select the volume in the same AZ as the SQL server that you intend to attach it to
  5. Select the check box to agree to the SLA and Submit
  6. Click Back to Server Console
  7. Attach the disk if necessary to the SQL instance
  8. Do this for all four volumes.

*HELPFUL LINKS:
Elastic Volume Service

Configure the Cluster

Prior to installing DataKeeper Cluster Edition, it is important to have Windows Server configured as a cluster using either a node majority quorum (if there is an odd number of nodes) or a node and file share majority quorum (if there is an even number of nodes). Consult the Microsoft documentation on clustering in addition to this topic for step-by-step instructions. Note: Microsoft released a hotfix for Windows 2008R2 that allows disabling of a node’s vote which may help achieve a higher level of availability in certain multi-site cluster configurations.

Add Failover Clustering

Add the Failover Clustering feature to both SQL instances.

  1. Launch Server Manager.
  2. Select Features in the left pane and click Add Features in the Features This starts the Add Features Wizard.
  3. Select Failover Clustering.
  4. Select Install.

Validate a Configuration

  1. Open Failover Cluster Manager.
  2. Select Failover Cluster Manager, select Validate a Configuration.
  3. Click Next, then add your two SQL instances.

Note: To search, select Browse, then click on Advanced and Find Now. This will list available instances.

  1. Click Next.
  2. Select Run Only Tests I Select and click Next.
  3. In the Test Selection screen, deselect Storage and click Next.
  4. At the resulting confirmation screen, click Next.
  5. Review Validation Summary Report then click Finish.

Create Cluster

  1. In Failover Cluster Manager, click on Create a Cluster then click Next.
  2. Enter your two SQL instances.
  3. On the Validation Warning page, select No then click Next.
  4. On the Access Point for Administering the Cluster page, enter a unique name for your WSFC Cluster. Then enter the Failover Clustering IP address for each node involved in the cluster. This is the first of the three secondary IP addresses added previously to each instance.
  5. IMPORTANT!Uncheck the “Add all available storage to the cluster” checkbox. DataKeeper mirrored drives must not be managed natively by the cluster. They will be managed as DataKeeper Volumes.
  6. Click Next on the Confirmation
  7. On Summary page, review any warnings then select Finish.

Configure Quorum/Witness

  1. Create a folder on your quorum/witness instance (witness).
  2. Share the folder.
    1. Right-click folder and select Share With / Specific People….
    2. From the dropdown, select Everyone and click Add.
    3. Under Permission Level, select Read/Write.
    4. Click Share, then Done. (Make note of the path of this file share to be used below.)
  3. In Failover Cluster Manager, right-click cluster and choose More Actions and Configure Cluster Quorum Settings. Click Next.
  4. On the Select Quorum Configuration, choose Node and File Share Majority and click Next.
  5. On the Configure File Share Witness screen, enter the path to the file share previously created and click Next.
  6. On the Confirmation page, click Next.
  7. On the Summary page, click Finish.

Install and Configure DataKeeper

After the basic cluster is configured but prior to any cluster resources being created, install and license DataKeeper Cluster Edition on all cluster nodes. See the DataKeeper Cluster Edition Installation Guide for detailed instructions.

  1. Run DataKeeper setup to install DataKeeper Cluster Edition on both SQL instances.
  2. Enter your license key and reboot when prompted.
  3. Launch the DataKeeper GUI and connect to server.

*Note: The domain or server account used must be added to the Local System Administrators Group. The account must have administrator privileges on each server that DataKeeper is installed on. Refer to DataKeeper Service Log On ID and Password Selection for additional information.

  1. Right click on Jobs and connect to both SQL servers.
  2. Create a Job for each mirror you will create. One for your DTC resource, and one for your SQL resource..
  3. When asked if you would like to auto-register the volume as a cluster volume, select Yes.

*Note: If installing DataKeeper Cluster Edition on Windows “Core” (GUI-less Windows), make sure to read Installing and Using DataKeeper on Windows 2008R2/2012 Server Core Platforms for detailed instructions.

Configure MSDTC

  1. For Windows Server 2012 and 2016, in the Failover Cluster Manager GUI, select Roles, then select Configure Role.
  2. Select Distributed Transaction Coordinator (DTC), and click Next.

*For Windows Server 2008, in the Failover Cluster Manager GUI, select Services and Applications, then select Configure a Service or Application and click Next.

  1. On the Client Access Point screen, enter a name, then enter the MSDTC IP address for each node involved in the cluster. This is the second of the three secondary IP addresses added previously to each instance. Click Next.
  2. Select the MSDTC volume and click Next.
  3. On the Confirmation page, click Next.
  4. Once the Summary page displays, click Finish.

Install SQL on the First SQL Instance

  1. On the domain controller server create a folder and share it..
    1. For example “TEMPSHARE” with Everyone permission.
  2. Create a sub folder “SQL” and copy the SQL .iso installer into that sub folder.
  3. On the SQL server, create a network drive and attach it to the shared folder on the domain controller.
    • . For example “net use S: \\\TEMPSHARE
  4. On the SQL server the S: drive will appear. CD to the SQL folder and find the SQL .iso installer. Right click on the .iso file and select Mount. The setup.exe installer will appear with the SQL .iso installer.

F:\>Setup /SkipRules=Cluster_VerifyForErrors /Action=InstallFailoverCluster

  1. On Setup Support Rules, click OK.
  2. On the Product Key dialog, enter your product key and click Next.
  3. On the License Terms dialog, accept the license agreement and click Next.
  4. On the Product Updates dialog, click Next.
  5. On the Setup Support Files dialog, click Install.
  6. On the Setup Support Rules dialog, you will receive a warning. Click Next, ignoring this message, since it is expected in a multi-site or non-shared storage cluster.
  7. Verify Cluster Node Configuration and click Next.
  8. Configure your Cluster Network by adding the “third” secondary IP address for your SQL instance and click Next. Click Yes to proceed with multi-subnet configuration.
  9. Enter passwords for service accounts and click Next.
  10. On the Error Reporting dialog, click Next.
  11. On the Add Node Rules dialog, skipped operation warnings can be ignored. Click Next.
  12. Verify features and click Install.
  13. Click Close to complete the installation process.

Install SQL on the Second SQL Instance

Installing the second SQL instance is similar to the first one.

  1. On the SQL server, create a network drive and attach it to the shared folder on the domain controller as explained above for the first SQL server.
  2. Once the .iso installer is mounted, run SQL setup once again from the command line in order to skip the Validate Open a Command window, browse to your SQL install directory and type the following command:

Setup /SkipRules=Cluster_VerifyForErrors /Action=AddNode /INSTANCENAME=”MSSQLSERVER”

(Note: This assumes you installed the default instance on the first node)

  1. On Setup Support Rules, click OK.
  2. On the Product Key dialog, enter your product key and click Next.
  3. On the License Terms dialog, accept the license agreement and click Next.
  4. On the Product Updates dialog, click Next.
  5. On the Setup Support Files dialog, click Install.
  6. On the Setup Support Rules dialog, you will receive a warning. Click Next, ignoring this message, since it is expected in a multi-site or non-shared storage cluster.
  7. Verify Cluster Node Configuration and click Next.
  8. Configure your Cluster Network by adding the “third” secondary IP address for your SQL Instance and click Next. Click Yes to proceed with multi-subnet configuration.
  9. Enter passwords for service accounts and click Next.
  10. On the Error Reporting dialog, click Next.
  11. On the Add Node Rules dialog, skipped operation warnings can be ignored. Click Next.
  12. Verify features and click Install.
  13. Click Close to complete the installation process.

Common Cluster Configuration

This section describes a common 2-node replicated cluster configuration.

  1. The initial configuration must be done from the DataKeeper UI running on one of the cluster nodes. If it is not possible to run the DataKeeper UI on a cluster node, such as when running DataKeeper on a Windows Core only server, install the DataKeeper UI on any computer running Windows XP or higher and follow the instruction in the Core Only section for creating a mirror and registering the cluster resources via the command line.
  2. Once the DataKeeper UI is running, connect to each of the nodes in the cluster.
  3. Create a Job using the DataKeeper UI. This process creates a mirror and adds the DataKeeper Volume resource to the Available Storage.

!IMPORTANT: Make sure that Virtual Network Names for NIC connections are identical on all cluster nodes.

  1. If additional mirrors are required, you can Add a Mirror to a Job.
  2. With the DataKeeper Volume(s)now in Available Storage, you are able to create cluster resources (SQL, File Server, etc.) in the same way as if there were a shared disk resource in the cluster. Refer to Microsoft documentation for additional information in addition to the above for step-by-step cluster configuration instructions.

Connectivity to the cluster (virtual) IPs

In addition to the Primary IP and secondary IP, you will also need to configure the virtual IP addresses in the Huawei Cloud so that they can be routed to the active node.

  1. From the Service List dropdown, select Elastic Cloud Server.
  2. Click on one of the SQL instance for which you want to add cluster virtual IP address (one for MSDTC, one for SQL Failover Cluster)
  3. Select NICs > Manage Virtual IP Address.
  4. Click on Assign Virtual IP address and select Manual enter an IP address that is within the subnet range for the instance (ex. For 15.0.1.25, enter 15.0.1.26). Click Ok.
  5. Click on the More dropdown on the IP address row, and select Bind to Server, select both the server to bind the IP address to, and the NIC card.
  6. Use the same steps 4. and 5 for the MSDTC and SQLFC virtual IPs
  7. Click OKto save your work.

Management

Once a DataKeeper volume is registered with Windows Server Failover Clustering, all of the management of that volume will be done through the Windows Server Failover Clustering interface. All of the management functions normally available in DataKeeper will be disabled on any volume that is under cluster control. Instead, the DataKeeper Volume cluster resource will control the mirror direction, so when a DataKeeper Volume comes online on a node, that node becomes the source of the mirror. The properties of the DataKeeper Volume cluster resource also display basic mirroring information such as the source, target, type and state of the mirror.

Troubleshooting

Use the following resources to help troubleshoot issues:

  • Troubleshooting issues section
  • For customers with a support contract – http://us.sios.com/support/overview/
  • For evaluation customers only – Pre-sales support

Additional Resources:

Step-by-Step: Configuring a 2-Node Multi-Site Cluster on Windows Server 2008 R2 – Part 1 — http://clusteringformeremortals.com/2009/09/15/step-by-step-configuring-a-2-node-multi-site-cluster-on-windows-server-2008-r2-%E2%80%93-part-1/

Step-by-Step: Configuring a 2-Node Multi-Site Cluster on Windows Server 2008 R2 – Part 3 — http://clusteringformeremortals.com/2009/10/07/step-by-step-configuring-a-2-node-multi-site-cluster-on-windows-server-2008-r2-%E2%80%93-part-3/

Filed Under: Blog posts, Clustering Simplified, Datakeeper Tagged With: #SANLess Clusters for SQL Server Environments, #SANLess Clusters for Windows Environments, disaster recovery, ECS, High Availability, Huawei Cloud, SQL Server Failover Cluster

Beginning Well is Great, But Maintaining Uptime Takes Vigilance

September 28, 2021 by Jason Aw Leave a Comment

Beginning Well is Great, But Maintaining Uptime Takes Vigilance


Beginning Well is Great, But Maintaining Uptime Takes Vigilance

Author Isabella Poretsis states, “Starting something can be easy, it is finishing it that is the highest hurdle.” It is great to have a kickoff meeting.  It is invigorating, and exciting. Managers and leaders look out at the greenfield with excitement and optimism is high.  But, this moment of kickoff, and even the Champagne popping moment of a successful deployment are but just the beginning. Maintaining uptime requires ongoing vigilance.

High availability and the elusive four nines of uptime for your critical applications and databases aren’t momentary occurrences, but rather, a constant endeavor to end the little foxes that destroy the vineyard.  Staying abreast of threats, up-to-date on the updates, and properly trained and prepared is the work from which your team “is never entitled to take a vacation.”

For those who want to stay vigilant in maintaining uptime, here are five tips:

1. Monitor the Environment 

Very little in enterprise software still follows the “set it and forget it” mindset.  Everything, since the day you uncorked the grand opening champagne to now, has been moving toward a state of decline.  If you aren’t monitoring the servers, workloads, network traffic, and hardware (virtual or physical), you may lose uptime and stability.

2. Perform Maintenance

One thing that I have always noticed in over twenty plus years of software development and services is that all software comes with updates.  Apply them.  Remember to execute sound maintenance policies, including taking and verifying backups. One tech writer suggested the only update you regret is the one you failed to make.

3. Learn Continuously

My first introduction to high availability came when I unplugged one end of the Token Ring for a server in our lab as an intern, fresh from the CE-211 lab.  The administrator was in my face in minutes.  After an earful, he gave me an education.  Ideally, you and your team want to learn without taking down your network, but you do absolutely want to keep learning.  Look into paid courses on existing technology, new releases, emerging infrastructure.  Check your vendors for courses and items related to your process, environment, software deployments and company enterprise.  Free courses for many things also exist if money is an issue.

4. Multiply the learning

In addition to continuous learning, make a plan to multiply the learning.  As the VP of Customer Experience at SIOS we have seen the tremendous difference between teams who share their learning and those who don’t.  Teams that share their learning avoid gaps in knowledge that compromise downtime.  The best way to know that you learned something is to teach it to somebody else. As you learn, share the learning with team members to reduce the risk of downtime due to error, and for that matter vacation.

5. End well . . .before the next beginning

All projects, servers, and software have an ending.  End well.  Decommission correctly.  Begin the next phase, deployment, software relationship, etc well by closing up loose ends, documenting what went well, what did not, and what to do next.  Treat your existing vendors well.  You just may need them again later.  Understand the existing systems and high availability solutions before proceeding with a new deployment.  This proper ending helps you begin again from a better starting place headed towards a stronger outcome.

Keeping the system highly available is a continuous process.  Set it and forget it is a nice catch phrase, but the reality is that uptime takes vigilance, continual monitoring, proper maintenance, and constant.

-Cassius Rhue, VP, Customer Experience

Reproduced with permission from SIOS

Filed Under: Clustering Simplified Tagged With: Application availability, clusters, disaster recovery, High Availability

  • « Previous Page
  • 1
  • …
  • 14
  • 15
  • 16
  • 17
  • 18
  • …
  • 26
  • Next Page »

Recent Posts

  • Fail Open vs. Fail Closed: Why It’s a False Dilemma (and How True HA Fixes It)
  • The 5-Step Checklist for Validating Your Failover Setup
  • Managing an Inherited DataKeeper Cluster: Challenges and Best Practices
  • Setting Up Nginx Load Balancer on AWS
  • With Great Power: Cluster Maintenance Best Practices

Most Popular Posts

Maximise replication performance for Linux Clustering with Fusion-io
Failover Clustering with VMware High Availability
create A 2-Node MySQL Cluster Without Shared Storage
SAP for High Availability Solutions For Linux
Bandwidth To Support Real-Time Replication
The Availability Equation – High Availability Solutions.jpg
Choosing Platforms To Replicate Data - Host-Based Or Storage-Based?
Guide To Connect To An iSCSI Target Using Open-iSCSI Initiator Software
Best Practices to Eliminate SPoF In Cluster Architecture
Step-By-Step How To Configure A Linux Failover Cluster In Microsoft Azure IaaS Without Shared Storage azure sanless
Take Action Before SQL Server 20082008 R2 Support Expires
How To Cluster MaxDB On Windows In The Cloud

Join Our Mailing List

Copyright © 2026 · Enterprise Pro Theme on Genesis Framework · WordPress · Log in