SIOS SANless clusters

SIOS SANless clusters High-availability Machine Learning monitoring

  • Home
  • Products
    • SIOS DataKeeper for Windows
    • SIOS Protection Suite for Linux
  • News and Events
  • Clustering Simplified
  • Success Stories
  • Contact Us
  • English
  • 中文 (中国)
  • 中文 (台灣)
  • 한국어
  • Bahasa Indonesia
  • ไทย

Cloud Witness To Build Multi-Instance SQL Server Failover Cluster In Azure

September 10, 2018 by Jason Aw Leave a Comment

New Azure ILB Feature Allows You To Build A Multi-Instance SQL Server Failover Cluster In Azure

New Azure ILB Feature Allows You To Build A Multi-Instance SQL Server Failover Cluster In Azure

The new feature, Cloud Witness is my favourite at the moment. Before we look at the new quorum features in Windows Server 2016, I think it is important to know where we came from. In my previous post Understanding the Windows Server Failover Cluster Quorum in Windows Server 2012 R2 I went into some great detail regarding the history and evolution of the cluster quorum. I suggest you review that post to understand how the quorum works in Windows Server 2012 R2. Also, how the new features of Windows Server 2016 are going to make your cluster deployments even more resilient.

Cloud Witness

A Cloud Witness allows you to leverage Azure Blob Storage to act as a witness for your cluster. This witness would be in place of a Disk Witness or File Share Witness. The configuration of a Cloud Witness is extremely easy. From my experience costs next to nothing to host in Azure. The only downside is that the cluster nodes will need to be able to communicate over the internet to with your Azure Blob Storage. Very often cluster nodes are forbidden to communicate over to the public internet. So you will need to coordinate with your security team if you want to enable a Cloud Witness.

There are many compelling reasons for using a Cloud Witness to build the Multi-Instance SQL Server Failover Cluster In Azure. But for me it makes most sense in three very specific environments: Failover Cluster in Azure, Branch Office Clusters, and Multisite Clusters.

On A Closer Look

Let’s take a look at each of these scenarios to see how a Cloud Witness can help.
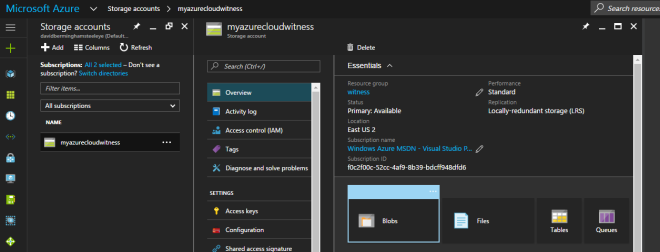
New ILB Feature For Multi-Instance SQL Server Failover Cluster In Azure
Figure 1 – When you’re trying to build Multi-Instance SQL Server Failover Cluster In Azure, the cloud witness storage account should always be configured Locally Redundant Storage (LRS)

Highly Available Deployments

If you are moving to Azure (or really any cloud provider), you will want to make sure your deployments are highly available. If you are taking about SQL Server, File Servers, SAP or other workloads traditionally clustered with Windows Server Failover Clustering, you will need to use either a File Share Witness or a Cloud Witness, since a Disk Witness is not possible in Azure. With Windows Server 2012 R2 or Windows Server 2008 R2, you will need to use a File Share Witness. Windows Server 2016 makes it possible to use a Cloud Witness. The advantage of a Cloud Witness is that you don’t have to maintain another Windows instance in Azure to host the File Share. Instead, Microsoft allows you to leverage Blob Storage.  This gives you a less expensive solution, one that is much easier to manage, and more resilient.

Location

When looking at cluster deployments in branch offices, cost and maintenance is always a consideration. For a retail chain with hundreds or thousands of locations, having a SAN in each location can be cost prohibitive. Each location might to run a two node Hyper-V cluster on a S2D Hyper-converged configuration or a 3rd party replication solution to host a number of virtual machines. Now what a Cloud Witness can do is to help the business avoid the cost of adding an additional physical server in each location to act as a File Share Witness or the cost of adding a SAN to each location.

Eliminates The Need For A 3rd Data Center

And finally, when deploying a multisite cluster, the Cloud Witness eliminates the need for a 3rd data center to host the File Share Witness. Before the introduction of the Cloud Witness, best practice would dictate that the File Share Witness reside in a 3rd location. Access to a 3rd datacenter just to host a file share witness was not always feasibly and certainly introduced another layer of complexity. By using a Cloud Witness you eliminate the need to maintain a 3rd location and access to the witness is done over the public internet, minimizing the network requirements as well.

Site Awareness

When building a multisite cluster, there has always been another common problem. Controlling the failover to always prefer the local site was not possible. While you could specify Preferred Owners, the Preferred Owners setting is commonly misunderstood. Administrators may not have realized this. But do you know even if they didn’t list a server as Preferred Owner, the server is automatically appended to the end of the Preferred Owners list maintained by the cluster. The result of this misunderstanding is that although you may have only listed the local servers as Preferred Owners, you could potentially have a cluster resource failover to the DR site. And this is even when there is a perfectly good node available in the local site. Obviously this is not what you expect and using Site Awareness will eliminate this problem moving forward.

Site Awareness fixes this problem by always preferring the local site when deciding which node to bring online. So in a normal circumstance a clustered workload will always failover to a local node unless you have a complete site outage. In which case one of the DR nodes will come online. The same holds true once you are running in the DR site. The cluster will recover the workload on a server in the DR site if it was previously running on a node in the DR site. Site Awareness will always prefer a local node.

Fault Domains

Building upon site awareness is Fault Domains. Fault Domains goes a step further and lets you define Node, Chasse, and Rack locations in addition to Site. Fault Domains have three benefits: Storage Affinity in a Stretch Cluster, increases Storage Spaces resiliency. It enhances the Health Services alerts by including meta data about the location of the associated resources raising the alarm. Storage Affinity will help ensure that your cluster workloads and storage are running in the same location. You certainly wouldn’t want your VM reading and writing data that is sitting on a CSV in a different city.

However, I think the biggest winner here is the Storage Spaces Direct (S2D) scenario. SD2 will leverage the information you provide about your cluster nodes location (Site, Rack, Chassis) to ensure that the multiple copies of data that is written for redundancy all live in different Fault Domains. This helps ensure that data placement is optimized so that the failure of a single Node, Chassis, Rack or Site does not bring down your entire S2D deployment.  Cosmos Darwin has an excellent video on Channel 9 that explains this concept in great detail.

Summary

Windows Server 2016 adds several new enhancements to the cluster quorum that will provide some immediate benefits to your cluster deployments. In addition, check out some of the other great new cluster enhancements like rolling system upgrade, Virtual Machine Resiliency, Workgroup and Multi-Domain Clusters and others.

To read about other tips such as building a new Multi-Instance SQL Server Failover Cluster In Azure with Cloud Witness, have a read at our posts.

Reproduced with permission from Clusteringformeremortals.com
Filed Under: Clustering Simplified Tagged With: Azure, Azure Resource Manager, Cloud Witness, cluster, Deployment, failover cluster, High Availability, Load Balance, multi instance sql server failover cluster in azure, PowerShell, replication, SQL Server, System Center Configuration Manager, Windows Server 2008, Windows Server 2012

Deploy 2-Node File Server Failover Cluster in Azure

August 22, 2018 by Jason Aw Leave a Comment

Deploy a highly available file server in Azure IAAS with SIOS Datakeeper

Deploying A Highly Available File Server In Azure IAAS (ARM) with SIOS DataKeeper

In this post we will detail the specific steps required to Deploy 2-Node File Server Failover Cluster in Azure in a single region of Azure using Azure Resource Manager. I will assume you are familiar with basic Azure concepts as well as basic Failover Cluster concepts. In this article we will cover what is unique about deploying a File Server Failover Cluster in Azure.

With DataKeeper Cluster Edition you are able to take the locally attached storage, whether it is Premium or Standard Disks, and replicate those disks either synchronously, asynchronously or a mix or both, between two or more cluster nodes. In addition, a DataKeeper Volume resource is registered in Windows Server Failover Clustering which takes the place of a Physical Disk resource. Instead of controlling SCSI-3 reservations like a Physical Disk Resource, the DataKeeper Volume controls the mirror direction, ensuring the active node is always the source of the mirror. As far as Failover Clustering is concerned, it looks, feels and smells like a Physical Disk and is used the same way Physical Disk Resource would be used.

Pre-Requisites To Deploy 2-Node File Server Failover Cluster in Azure

  • You have used the Azure Portal before and are comfortable deploying virtual machines in Azure IaaS.
  • Have obtained a license or eval license of SIOS DataKeeper

Deploying A File Server Failover Cluster Instance Using The Azure Portal

To Deploy 2-Node File Server Failover Cluster in Azure, we are going to assume you have a basic Virtual Network based on Azure Resource Manager and you have at least one virtual machine up and running and configured as a Domain Controller. Once you have a Virtual Network and a Domain configured, you are going to provision two new virtual machines which will act as the two nodes in our cluster.

Our environment will look like this:

DC1 – Our Domain Controller and File Share Witness
SQL1 and SQL2 – The two nodes of our File Server Cluster

Provisioning The Two Cluster Nodes (SQL1 And SQL2)

Using the Azure Portal, we will provision both SQL1 and SQL2 exactly the same way. There are numerous options to choose from including instance size, storage options, etc. This guide is not meant to be an exhaustive guide to deploying Servers in Azure as there are some really good resources out there and more published every day. However, there are a few key things to keep in mind when creating your instances, especially in a clustered environment.

Availability Set – It is important that both SQL1, SQL2 AND DC1 reside in the same availability set. By putting them in the same Availability Set we are ensuring that each cluster node and the file share witness reside in a different Fault Domain and Update Domain. This helps guarantee that during both planned maintenance and unplanned maintenance the cluster will continue to be able to maintain quorum and avoid downtime.

Deploy 2-Node File Server Failover Cluster in Azure
Figure 3 – Be sure to add both cluster nodes and the file share witness to the same Availability Set

Static IP Address

Once each VM is provisioned, you will want to go into the setting and change the settings so that the IP address is Static. We do not want the IP address of our cluster nodes to change.

Deploy 2-Node File Server Failover Cluster in Azure
Figure 4 – Make sure each cluster node uses a static IP

Storage

As far as Storage is concerned, you will want to consult Performance best practices for SQL Server in Azure Virtual Machines. In any case, you will minimally need to add at least one additional disk to each of your cluster nodes. DataKeeper can use Basic Disk, Premium Storage or even Storage Pools consisting of multiple disks in a storage pool. Just be sure to add the same amount of storage to each cluster node and configure it identically. Also, be sure to use a different storage account for each virtual machine to ensure that a problem with one Storage Account does not impact both virtual machines at the same time.

Deploy 2-Node File Server Failover Cluster in Azure
Figure 5 – make sure to add additional storage to each cluster node

Create The Cluster

Assuming both cluster nodes (SQL1 and SQL2) have been provisioned as described above and added to your existing domain, we are ready to create the cluster. Before we create the cluster, there are a few Features that need to be enabled. These features are .Net Framework 3.5 and Failover Clustering. These features need to be enabled on both cluster nodes. You will also need to enable the FIle Server Role.

Deploy 2-Node File Server Failover Cluster in Azure
Figure 6 – enable both .Net Framework 3.5 and Failover Clustering features and the File Server on both cluster nodes

Once that role and those features have been enabled, you are ready to build your cluster. Most of the steps I’m about to show you can be performed both via PowerShell and the GUI. However, I’m going to recommend that for this very first step you use PowerShell to create your cluster. If you choose to use the Failover Cluster Manager GUI to create the cluster, you will find that you wind up with the cluster being issues a duplicate IP address.

Details To Note

Without going into great detail, what you will find is that Azure VMs have to use DHCP. By specifying a “Static IP” when we create the VM in the Azure portal all we did was create sort of a DHCP reservation. It is not exactly a DHCP reservation because a true DHCP reservation would remove that IP address from the DHCP pool. Instead, specifying a Static IP in the Azure portal simply means that if that IP address is still available when the VM requests it, Azure will issue that IP to it. However, if your VM is offline and another host comes online in that same subnet it very well could be issued that same IP address.

There is another strange side effect to the way Azure has implemented DHCP. When creating a cluster with the Windows Server Failover Cluster GUI when hosts use DHCP (which they have to), there is not option to specify a cluster IP address. Instead it relies on DHCP to obtain an address. The odd thing is, DHCP will issue a duplicate IP address, usually the same IP address as the host requesting a new IP address. The cluster will usually complete, but you may have some strange errors and you may need to run the Windows Server Failover Cluster GUI from a different node in order to get it to run. Once you get it to run you will want to change the cluster IP address to an address that is not currently in use on the network.

Avoid The Mess

You can avoid that whole mess by simply creating the cluster via Powershell and specifying the cluster IP address as part of the PowerShell command to create the cluster.

You can create the cluster using the New-Cluster command as follows:

New-Cluster -Name cluster1 -Node sql1,sql2 -StaticAddress 10.0.0.101 -NoStorage

After the cluster creation completes, you will also want to run the cluster validation by running the following command:

Test-Cluster

Deploy 2-Node File Server Failover Cluster in Azure
Figure 7 – The output of the cluster creation and the cluster validation commands

Create File Share Witness

Because there is no shared storage, you will need to create a file share witness on another server in the same Availability Set as the two cluster nodes. By putting it in the same availability set you can be sure that you only lose one vote from your quorum at any given time. If you are unsure how to create a File Share Witness you can review this article http://www.howtonetworking.com/server/cluster12.htm. In my demo I put the file share witness on domain controller. I have published an exhaustive explanation of cluster quorums at https://blogs.msdn.microsoft.com/microsoft_press/2014/04/28/from-the-mvps-understanding-the-windows-server-failover-cluster-quorum-in-windows-server-2012-r2/

Install DataKeeper

After the cluster is created it is time to install DataKeeper. It is important to install DataKeeper after the initial cluster is created so the custom cluster resource type can be registered with the cluster. If you installed DataKeeper before the cluster is created you will simply need to run the install again and do a repair installation.

Deploy 2-Node File Server Failover Cluster in Azure
Figure 8 – Install DataKeeper after the cluster is created

During the installation you can take all of the default options.  The service account you use must be a domain account and be in the local administrators group on each node in the cluster.

Deploy 2-Node File Server Failover Cluster in Azure
Figure 9 – the service account must be a domain account that is in the Local Admins group on each node

Once DataKeeper is installed and licensed on each node you will need to reboot the servers.

Create The DataKeeper Volume Resource

To create the DataKeeper Volume Resource you will need to start the DataKeeper UI and connect to both of the servers.
Deploy 2-Node File Server Failover Cluster in Azure

Connect to SQL1
Deploy 2-Node File Server Failover Cluster in Azure

Connect to SQL2
Deploy 2-Node File Server Failover Cluster in Azure

Once you are connected to each server, you are ready to create your DataKeeper Volume. Right click on Jobs and choose “Create Job”
Deploy 2-Node File Server Failover Cluster in Azure

Give the Job a name and description.
Deploy 2-Node File Server Failover Cluster in Azure

Choose your source server, IP and volume. The IP address is whether the replication traffic will travel.
Deploy 2-Node File Server Failover Cluster in Azure

Choose your target server.
Deploy 2-Node File Server Failover Cluster in Azure

Choose your options. For our purposes where the two VMs are in the same geographic region we will choose synchronous replication. For longer distance replication you will want to use asynchronous and enable some compression.
Deploy 2-Node File Server Failover Cluster in Azure

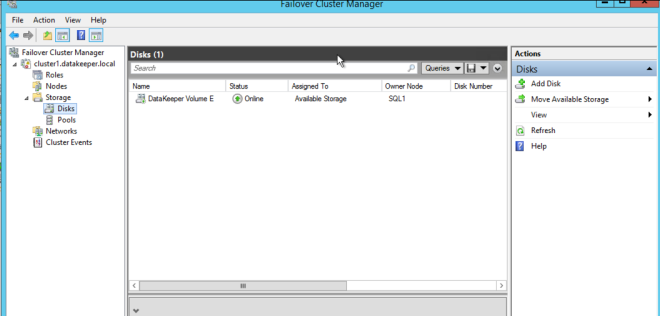
By clicking yes at the last pop-up you will register a new DataKeeper Volume Resource in Available Storage in Failover Clustering.

You will see the new DataKeeper Volume Resource in Available Storage.
Deploy 2-Node File Server Failover Cluster in Azure

Create The File Server Cluster Resource

To create the File Server Cluster Resource we will use Powershell once again rather than the Failover Cluster interface. The reason being is that once again because the virtual machines are configured to use DHCP, the GUI based wizard will not prompt us to enter a cluster IP address and instead will issue a duplicate IP address. To avoid this we will use a simple powershell command to create the FIle Server Cluster Resource and specify the IP Address

Add-ClusterFileServerRole -Storage "DataKeeper Volume E" 
-Name FS2 -StaticAddress 10.0.0.201

Make note of the IP address you specify here. It must be a unique IP address on your network. We will use this same IP address later when we create our Internal Load Balancer.

Create The Internal Load Balancer

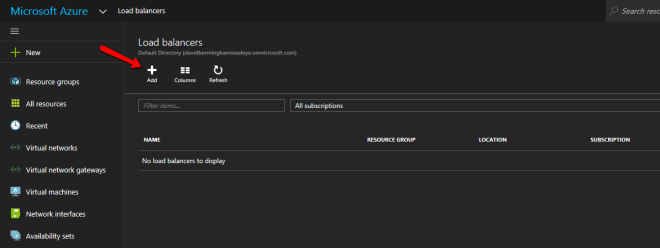
Here is where failover clustering in Azure is different than traditional infrastructures. The Azure network stack does not support gratuitous ARPS. Clients cannot connect directly to the cluster IP address. Instead, clients connect to an internal load balancer and are redirected to the active cluster node. What we need to do is create an internal load balancer. This can all be done through the Azure Portal as shown below.

First, create a new Load Balancer
Deploy 2-Node File Server Failover Cluster in Azure

You can use an Public Load Balancer if your client connects over the public internet, but assuming your clients reside in the same vNet, we will create an Internal Load Balancer. The important thing to take note of here is that the Virtual Network is the same as the network where your cluster nodes reside. Also, the Private IP address that you specify will be EXACTLY the same as the address you used to create the SQL Cluster Resource.
Deploy 2-Node File Server Failover Cluster in Azure

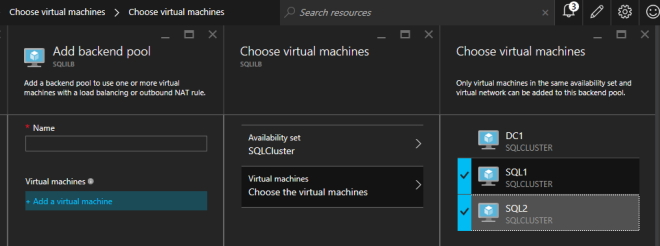
After the Internal Load Balancer (ILB) is created, you will need to edit it. The first thing we will do is to add a backend pool. Through this process you will choose the Availability Set where your SQL Cluster VMs reside. However, when you choose the actual VMs to add to the Backend Pool, be sure you do not choose your file share witness. We do not want to redirect SQL traffic to your file share witness.
Deploy 2-Node File Server Failover Cluster in Azure

The next thing we will do is add a Probe. The probe we add will probe Port 59999. This probe determines which node is active in our cluster.
Deploy 2-Node File Server Failover Cluster in Azure

And then finally, we need a load balancing rule to redirect the SMB traffic, TCP port 445. The important thing to notice in the screenshot below is the Direct Server Return is Enabled. Make sure you make that change.

Deploy 2-Node File Server Failover Cluster in Azure

Fix The File Server IP Resource

Almost there to Deploy 2-Node File Server Failover Cluster in Azure! The final step in the configuration is to run the following PowerShell script on one of your cluster nodes. This will allow the Cluster IP Address to respond to the ILB probes and ensure that there is no IP address conflict between the Cluster IP Address and the ILB. Please take note; you will need to edit this script to fit your environment. The subnet mask is set to 255.255.255.255, this is not a mistake, leave it as is. This creates a host specific route to avoid IP address conflicts with the ILB.

# Define variables
$ClusterNetworkName = “” 
# the cluster network name 
(Use Get-ClusterNetwork on Windows Server 2012 of higher to find the name)
$IPResourceName = “” 
# the IP Address resource name 
$ILBIP = “” 
# the IP Address of the Internal Load Balancer (ILB)
Import-Module FailoverClusters
# If you are using Windows Server 2012 or higher:
Get-ClusterResource $IPResourceName | Set-ClusterParameter 
-Multiple @{Address=$ILBIP;ProbePort=59999;SubnetMask="255.255.255.255";
Network=$ClusterNetworkName;EnableDhcp=0}
# If you are using Windows Server 2008 R2 use this: 
#cluster res $IPResourceName /priv enabledhcp=0 address=$ILBIP probeport=59999  
subnetmask=255.255.255.255

Creating File Shares

You will find that using the File Share Wizard in Failover Cluster Manager does not work. Instead, you will simply create the file shares in Windows Explorer on the active node. Failover clustering automatically picks up those shares and puts them in the cluster.

Note that the”Continuous Availability” option of a file share is not supported in this configuration.

Conclusion

You have managed to Deploy 2-Node File Server Failover Cluster in Azure.  If you have ANY problems, please reach out to me on Twitter @daveberm and I will be glad to assist. If you need a DataKeeper evaluation key fill out the form at http://us.sios.com/clustersyourway/cta/14-day-trial and SIOS will send an evaluation key sent out to you.

Reproduced with permission from Clusteringformeremortals.com

Filed Under: Clustering Simplified, Datakeeper Tagged With: Azure, deploy 2 node file server failover cluster in azure, failover cluster

Why Build A SQL server Failover Cluster Instance In Azure Cloud?

March 13, 2018 by Jason Aw Leave a Comment

Why Would You Want To Build A SQL server Failover Cluster Instance In The Azure Cloud?

There was an interesting discussion happening today in the Twitterverse. Basically, someone asked the question “Has anyone set up a SQL server Failover Cluster Instance in Azure?” The ensuing conversation involved some well respect SQL Server experts. And it led to the following question, “Why would you want to build a SQL Server AlwaysOn Failover Cluster instance in the cloud?”

That question could be interpreted in two ways: “Why do you need High Availability in the Cloud” or “Why wouldn’t you use AlwaysOn Availability Groups instead of Failover Cluster Instances?”

Let’s address each question one at a time.

Question 1 – Why do you need High Availability in the Azure Cloud?

  • You might think that just because you host your SQL Server instance in Azure, that you are covered by their 99.95% uptime SLA. If you think that, you would be wrong. In order to take advantage of the 99.95% SLA, you have to have at least two instances of SQL running in an Availability Set. With a single instance of SQL running, you can definitely expect that there will minimally be downtime during maintenance periods. But, you are also susceptible to unplanned failures.
  • Two instances of SQL Server cannot generally be load balanced. You have to implement some sort of mechanism to keep the servers in sync. To ensure that if there is a problem with one of the servers, the other server will be able to continue to service the requests. High Availability solutions like AlwaysOn Availability Groups, AlwaysOn Failover Cluster Instances and even the deprecated Database Mirroring can provide high availability for SQL Server in that scenario. Other solutions like log shipping and transactional replication may be able to help keep data synchronized between servers. But they are not typically considered high availability solutions and will not ensure the availability of your SQL Server.
  • Microsoft does occasionally need to perform maintenance on Azure that could bring down an entire Upgrade Domain and all the instances running in that Upgrade Domain. You don’t have any say on when this will happen. So, you need to have a mechanism in place to ensure that if they do have to bring down your primary SQL Server instance, you can expect that your secondary SQL Server instance will take over the workload without missing a beat. All of the high availability solutions mentioned above can ensure that you will continue to run in the event that Microsoft is doing maintenance on the Upgrade Domain of your primary server. Microsoft will only do maintenance on a single Upgrade Domain at a time. This ensures that your secondary server will still be online assuming you put the both in the same Availability Set.
  • What do you do if YOU want to performance maintenance on your production SQL Server? Maybe you want to install a Service Pack or other hotfix? Without a secondary server to fail over to, you will have to schedule planned downtime. One of the primary benefits of any high availability solution is the ability to do rolling upgrades, minimizing the impact of planned downtime.

Question 2 – Why wouldn’t you use AlwaysOn Availability Groups instead of Failover Cluster Instances?

  • Save Money! SQL Server AlwaysOn Availability Groups requires Enterprise Edition of SQL Server. Why not save money and deploy SQL Server Standard Edition and build a simple 2-node Failover Cluster Instance? Unless you need Enterprise Edition for some other reason, this is a no brainer.
  • Protect the ENTIRE SQL Server instance. AlwaysOn Availability Groups only protects user defined databases; you cannot protect the System and MSDB databases. If you build a SQL Server Failover Cluster Instance instead, you are protecting the ENTIRE instance, including the System and MSDB databases.
  • Ease Administration. In Azure, you are limited to just on client listener. This limits you to just one Availability Group. In contrast, with a Failover Cluster Instance one client listener is all you need, so there is no limitation.
  • Worker Thread Exhaustion. With AlwaysOn AG, you have to keep an eye on the available worker threads. The available worker threads limit the number of databases you can protect with AlwaysOn AG. In contrast, AlwaysOn Failover Clustering with DataKeeper block level replication does not consume more resources for each database you add. This means you can scale to protect hundreds of databases without the additional overhead associated with AlwaysOn AG.
  • Distribute Transaction Support. AlwaysOn AG does not support distributed transactions (DTC). If your application requires DTC support, you are going to have to look at an AlwaysOn Failover Cluster Instance instead.
  • Support of Other Replication Technologies. If you plan on setting up Peer to Peer replication between two databases protected by AlwaysOn AG you can forget about it. In fact, there are many restrictions you have to be aware of once you deploy AlwaysOn Availability Groups. AlwaysOn FCI’s do not have any of those restrictions.

Conclusion

Knowing what you know above, shouldn’t the question really be “Why would I want to implement AlwaysOn AG in the Cloud when I can have a much more robust and inexpensive solution building an AlwaysOn Failover Cluster instance?”

If you are interested in building an AlwaysOn Failover Cluster Instance in Azure, check out my blog post Step-by-Step: How to configure a SQL Server Failover Cluster Instance (FCI) in Microsoft Azure IaaS #SQLServer #Azure #SANLess

Reproduced with permission from https://clusteringformeremortals.com/2015/03/05/why-would-you-want-to-build-a-sqlserver-failover-cluster-instance-in-the-azure-cloud/

Filed Under: Clustering Simplified Tagged With: failover cluster, High Availability, SQL Server Failover Cluster, SQL Server Failover Cluster Instance

Windows Server 10 Storage Replica Configuration And Failover Cluster

March 7, 2018 by Jason Aw Leave a Comment

Windows Server 10 Storage Replica Configuration And First Impressions

Exciting New Feature – Storage Replicas!

One of the most exciting new features in Windows Server 10 announced by Microsoft is Storage Replicas. It is described by Microsoft here: http://technet.microsoft.com/en-us/library/dn765475.aspx#BKMK_SR. And further down the article, I’ll also look at failover clusters.

“Storage Replica (SR) is a new feature that enables storage-agnostic, block-level, synchronous replication between servers for disaster recovery, as well as stretching of a failover cluster for high availability. Synchronous replication enables mirroring of data in physical sites with crash-consistent volumes ensuring zero data loss at the file system level. Asynchronous replication allows site extension beyond metropolitan ranges with the possibility of data loss.

What value does this change add?

Storage Replication enables you to do the following:

Provide an all-Microsoft disaster recovery solution for planned and unplanned outages of mission-critical workloads.

Use SMB3 transport with proven reliability, scalability, and performance.

Stretch clusters to metropolitan distances.

Use Microsoft software end to end for storage and clustering, such as Hyper-V, Storage Replica, Storage Spaces, Cluster, Scale-Out File Server, SMB3, Deduplication, and ReFS/NTFS.

Help reduce cost and complexity as follows:

Hardware agnostic, with no requirement to immediately abandon legacy storage such as SANs.

Allows commodity storage and networking technologies.

Features ease of graphical management for individual nodes and clusters through Failover Cluster Manager and Microsoft Azure Site Recovery.

Includes comprehensive, large-scale scripting options through Windows PowerShell.

Helps reduce downtime, and increase reliability and productivity intrinsic to Windows.

Provide supportability, performance metrics, and diagnostic capabilities.”

What About Other Use Cases?

They mention a lot of use cases “… Hyper-V, Storage Replica, Storage Spaces, Cluster, Scale-Out File Server, SMB3, Deduplication, and ReFS/NTFS”. I’m not even sure what they mean by listing technologies such as ReFS/NTFS, Deduplication, SMB3, Storage Replica, Storage Spaces. These seem more like features rather than use cases, which I’m going to assume they are.

But let’s look at some of the other use cases they mentioned: Hyper-V, Cluster, Scale-out-File Server. I can easily imagine how Storage Replica is going to enhance these use cases by enabling shared nothing Scale-Out-File Servers and multisite clusters, including Hyper-V, SQL Server, File Servers, etc. In some cases it can also enable SANLess local area network clusters, allowing clusters to be built without requiring a shared Physical Disk resource.

Let’s Look At Failover Clusters

In my first look at this solution, I decided to focus on what I know and love, failover clusters. To keep things easy I decided I was going to focus on building a simple two node traditional file server (not scale out file server). I will start with three fresh VMs in an entirely pure Windows Server 10 domain.

Getting Started

It was easy enough to download the ISO’s and then install onto my 3 VMs went surprisingly fast. Promoting a DC was a pretty similar experience to 2012 R2. Although I think it was made a little more obvious that you have to actually run the DCPromo after the AD feature was installed.

I got my domain installed and my basic two node cluster with no resources built without a problem. Next, I used VMware Fusion as my Hypervisor since it supports nested Hypervisors (a feature sorely lacking in Hyper-V for testing and demo by the way). Then, I added a few additional VMDK files to each VM in my cluster and formatted them as E: and F: on each VM, figuring these would be my replica volumes. Another point to note, I had not defined resources yet and the cluster had no shared storage. Perfect, ready to start configuring Storage Replica!

And The Replication Process Kicks Off

So I fire up the Failover Cluster Manager and start poking around to see how I could start the replication process. There was absolutely nothing in the UI that I could find that said, Replica, Replication or anything even close to that. Because the documentation hadn’t shipped and the bits had only become available a few hours ago I was on my own to figure it out, despite my desperate Twitter searches for a how to blog. No problem I said, I’m a cluster MVP and my specialty is replication and multisite clusters so I’ll figure this out.

After a little searching I find that there is a new feature called Windows Volume Replication.

Windows Server 10 Storage Replica Configuration And First Impressions

Uh. What’s Happening?

Great, so I enable that on both nodes thinking this is going to be great, but still nothing is jumping out at me in the Windows Failover Cluster UI that says “Configure Replica”. Scratching my head some more and trying to reach out to a few smart people I still had no clue. Then it dawned on me…”maybe it only supports Cluster Disk?” Now the feature announcement says “supports commodity storage”. To me that means any old hard drive in my PC or in this case the attached virtual disk on my VMs. As it turns out, I was correct; the disk has to appear in the cluster as a Physical Disk Resource in Available Storage.

Getting Somewhere Finally

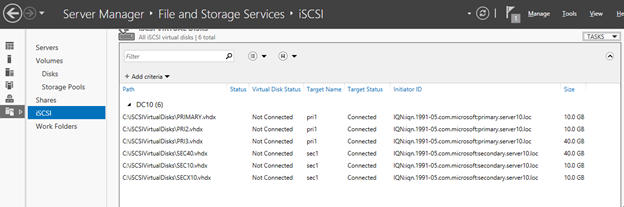
OK, not the greatest requirement, but I continued plugging away. To get some disks that could be added as Physical Disk Resources attached to my VMs I enabled the iSCSI target role on my DC and create two iSCSI Virtual Disks for each of my VMs. Now remember, this is not like a regular cluster so each of these virtual disks were only assigned to one VM, they were not shared.

Windows Server 10 Storage Replica Configuration And First Impressions

One each VM I used the iSCSI initiator to connect to these disks, initialized, onlined and formatted them. I then used Failover Cluster Manager to add them to the cluster.

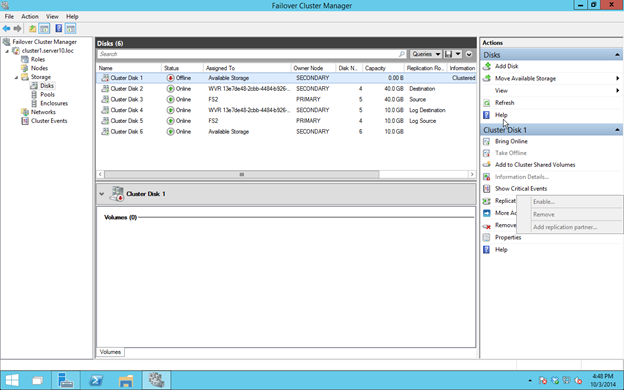
Finally, I see some new options for replication.

I still struggled for a while to get the Replication enable button to even become selectable.

Must Know!

Here are the IMPORT things you need to know to get this show on the road:

  • The Disk must be Physical Dis Resources in the cluster. This means they must support SCSI3 reservations and must pass cluster validation.
  • The Disk must be GPT, not MBR
  • Each Disk you want to replicate must have an associated Disk to be used for the “Log File”. I assume this is where they queue data when replication is interrupted or in asynchronous mirrors where the data can be slightly behind
  • You must add the disk (just the data disk, not the log disk) to a cluster resource BEFORE your can enable replication. You cannot enable replication on a disk that is sitting in Available Storage
  • Your Source and Target Servers must have the same size disks and volume letters

Enabling Replication

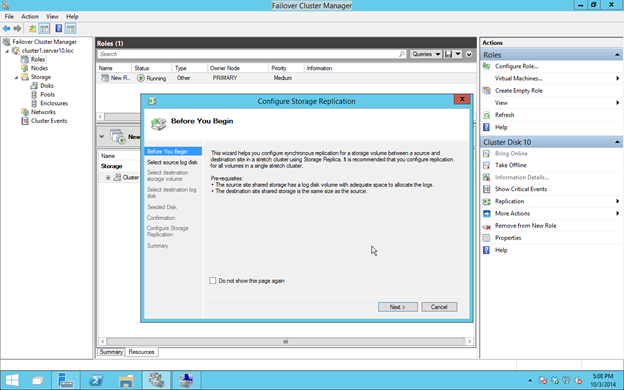
Once you do that you will finally be able to enable Replication.

Like I said, you will need to choose a source log disk that needs to be in available storage. Microsoft recommends a SSD disks. I don’t know how big it should be. I assume the bigger it is the longer replication can be interrupted before you consume all the space and break your mirror.

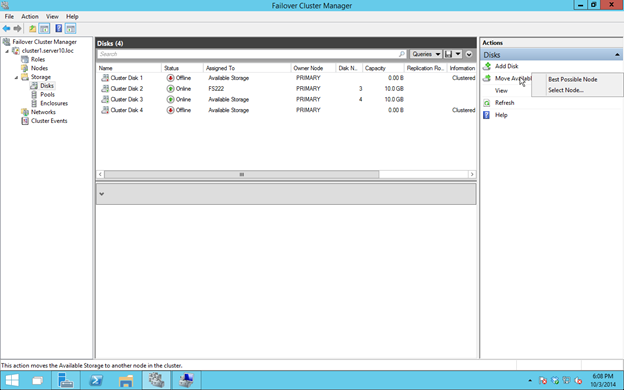
Next step is to choose the Disk on your target server. If you get a message like “No Storage Available” you probably need to move “Available Storage” so that the target disk is Online on the Secondary server.

Make sure nothing in the Technical Preview the Move Available Storage seems to be broken if you choose “Select Node”. However, if you choose “Best Possible Node” and things seem to work. Available Storage will come online on the SECONDARY server.

Now all Available Storage should be online on the SECONDARY server.


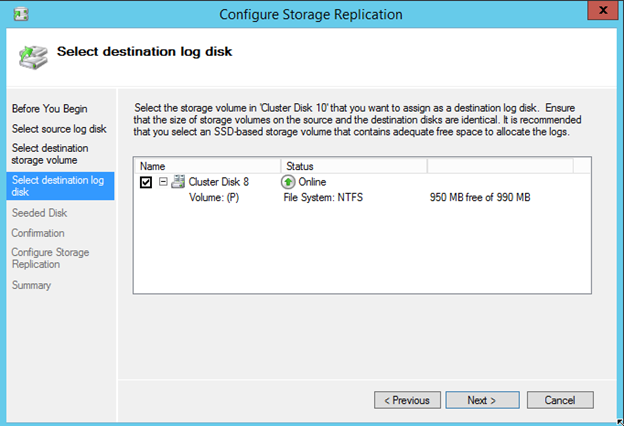
And a disk for the target’s log file

This looks like a nice feature, especially for WAN replication. Apparently you can seed to destination disk, avoiding a full sync over the WAN.

The next screen just confirms everything…

Failover Cluster Manager – When All Is Said And Done

Your cluster should look like this. You’ll probably notice that the Replication status displays “Unknown”. I’m assuming that is a bug that will be addressed later.

Failover Cluster Manager

The Other Bug

I noticed that the File Share creation wizard that is available via the Failover Cluster Manager doesn’t seem to work. It just closes unexpectedly after you launch it. However, you can create shares on the active node using File Manager and it will automatically be added to the cluster.

Some basic testing seems to indicate that Failover Cluster Manager works fine. Just be careful that you know which of your volumes are the replicated data volumes and which ones are the log volumes. Data written to the log files is not replicated, so if you make a mistake (like I did) you may think replication is not working.

And finally, after all this trial and error I come to find that Microsoft has started to post at least a few pointers on how to make this work. Check out the requirements in this post from Ned Pyle, Storage Replica PM.

http://social.technet.microsoft.com/Forums/windowsserver/en-US/f843291f-6dd8-4a78-be17-ef92262c158d/getting-started-with-windows-volume-replication?forum=WinServerPreview&prof=required

My Thoughts…

I reserve my thoughts until I have some more time to play with this feature…

Reproduced with permission from https://clusteringformeremortals.com/2014/10/04/windows-server-10-storage-replica-configuration-and-first-impressions-windows10/

Filed Under: Clustering Simplified Tagged With: failover cluster, storage replica, storage replication

New Features of Windows Server Failover Clustering

February 3, 2018 by Jason Aw Leave a Comment

New Features of Windows Server Failover Clustering

Elden Christensen recently blogged about some of the new features of Windows Server Failover Clustering in Windows Server 8. You can read the entire post here

All of these features found in Windows Server Failover Clustering in Windows Server 8 are welcome additions. My personal favorite is the “Dynamic Clusters” or what I think is probably better described as “Dynamic Quorum”. It basically allows the quorum to reconfigure itself dynamically which I think is a fantastic feature! If configured properly, you could actually withstand the failure of all but one remain node (last man standing) and still have a functional cluster. Previously this was only possible if you used the “Disk Only” quorum model, which is not recommended as the disk quorum represented a single point of failure.

With the new dynamic quorum model as nodes are removed from the cluster, the remaining nodes reconfigure themselves in the most resilient manner. For example, previously you had a 5 node cluster using the “Node Majority” quorum model. If you lose three nodes, the remaining two nodes would shut down as they no longer had a majority vote (2 out of 5 is not a majority). With the new model, as nodes leave the cluster, the quorum reconfigures itself so that the remaining two nodes would remain online.

The description above is really an over simplification of what actually happens under the covers. I plan to write more about it in the future, but it is definitely a welcome feature to check out!

For More Information

There are a few other blog articles relevant to Windows Server Failover Clustering you should refer to

How to Enable Failover Clustering and Network Load Balancing PowerShell Help on Windows Server “8”:

http://blogs.msdn.com/b/clustering/archive/2012/03/21/10286213.aspx

How to Enable CSV Cache:

http://blogs.msdn.com/b/clustering/archive/2012/03/22/10286676.aspx

How to Create a Cluster in a Restrictive Active Directory Environment:

http://blogs.msdn.com/b/clustering/archive/2012/03/30/10289577.aspx

Reproduced with permission from Clusteringformeremortals


Filed Under: Clustering Simplified Tagged With: Clustering, failover, failover cluster, failover clustering, Windows Server 8, Windows Server Failover Clustering

  • « Previous Page
  • 1
  • 2
  • 3
  • Next Page »

Recent Posts

  • Managing an Inherited DataKeeper Cluster: Challenges and Best Practices
  • Setting Up Nginx Load Balancer on AWS
  • With Great Power: Cluster Maintenance Best Practices
  • AI Is Moving Fast. Critical Applications Still Need to Stay Up.
  • What Is High Availability (HA)?

Most Popular Posts

Maximise replication performance for Linux Clustering with Fusion-io
Failover Clustering with VMware High Availability
create A 2-Node MySQL Cluster Without Shared Storage
SAP for High Availability Solutions For Linux
Bandwidth To Support Real-Time Replication
The Availability Equation – High Availability Solutions.jpg
Choosing Platforms To Replicate Data - Host-Based Or Storage-Based?
Guide To Connect To An iSCSI Target Using Open-iSCSI Initiator Software
Best Practices to Eliminate SPoF In Cluster Architecture
Step-By-Step How To Configure A Linux Failover Cluster In Microsoft Azure IaaS Without Shared Storage azure sanless
Take Action Before SQL Server 20082008 R2 Support Expires
How To Cluster MaxDB On Windows In The Cloud

Join Our Mailing List

Copyright © 2026 · Enterprise Pro Theme on Genesis Framework · WordPress · Log in